Despite broad browser support, container queries remain surprisingly underused and frequently misunderstood. Let’s look at how they differ from media queries, when to reach for each, and how container queries help reusable components respond naturally to the contexts in which they appear.
To be completely honest with you, I missed the news when CSS Container Queries first shipped. And when I finally heard about it, my very first thought was, “Why exactly do I need this when media queries already exist?”
I’m not proud of that reaction, knowing what I know now, but it was comforting to know that I wasn’t alone. In fact, there are legions of us out there.
What baffles me is that container queries aren’t a new feature, as it currently sits at around 94% browser support. And yet, very few people are actually using it. According to the State of CSS survey, 86% of developers are aware of container queries, but only 41.4% actually use them. Surveys can be biased and not completely representative of our entire field, but this one is certainly the best indicator we’ve got.
I’m not particularly interested in how many people are using container queries as much as in how they are using them. I can’t account for everyone, but from what I’ve seen — including in my own early attempts — many of us are using them wrong.
The bottom line is that incorrect use comes down to the same impression I had when learning about them: they absolutely look just like media queries at first glance. And since they look similar, it’s easy to assume they serve similar purposes and work the same way.
They don’t.
Note: I should state up front that what I’m focusing on in this article is using container size queries, i.e., a responsive design technique for responding to the size of a particular container. There are also container style queries that respond to a container’s computed styles (and are experimental at the time of this writing). You can catch up on those in Juan Diego’s piece here on Smashing Magazine where he examines their possible use cases
The viewport is a proxy. It always has been. Media queries are what gave us the illusion that screen width alone is responsible for how responsive apps adapt to their environment.
Ask yourself this: When you write @media, what are you asking the browser?
@media(min-width: 1024px){.card{display: flex;}
I, like most developers, am asking the browser: How wide is the screen right now? That’s it.
Media queries answer that beautifully, but what happens when this .card component is placed in a grid cell that’s 300px wide on a 1920px desktop screen?
The media query doesn’t care; it does its job. The viewport is still 1920px, so min-width: 1024px fires and the matched query styles are applied, even though the card only has 300px of space to work with. Eventually, everything in the card deforms, overflows, or cramps up.
“Media queries are dumb. Not dumb in terms of the concept, but dumb in that they don’t know very much. In fact, most people assume that they know more than they do.”
It’s common to think of responsive design purely as a system for updating complete page layouts, like going from two columns on a large screen to a single column on a small screen.
Container queries are smarter than that. They make responsive layouts more reliant on what’s happening inside a component rather than on the outer context that has no insight into a component’s contents. It is more like: “How much space is available for me in this specific spot, right now?”
Here is the same card code example we looked at in the last section, but with a container query:
This changes everything. The card isn’t influenced by the viewport; its only concern is whether the .card component’s parent wrapper has at least 450px of inline (i.e., horizontal in a left-to-right writing mode) space. If that condition is true, the component goes horizontal; if not, it goes to its default block display.
A very interesting way to distinguish @media and @container queries is the layout type.
Media queries are for the “macro” layout; they look outward. Stuff like page structure, the header that spans the window, footers, main grid layout, system preferences (prefers-color-scheme), device capabilities (touch screens). You know, anything that is majorly true to the entire page structure.
Container queries, I’d say, are for “micro” layouts, i.e., most things that live inside the “macro” layout. We use them when any content needs to responsively fit whatever space it is allocated. Components that come to mind are things like cards, widgets, forms, navigation, and so on.
In other words, think “page layout” vs. “component layout”.
An element shouldn’t magically become “tablet-sized” just because the width exceeds an abstract width threshold like 768px. Instead, it should switch layout when it has enough space to do so, whether that happens on a mobile viewport or inside a desktop sidebar.
Responsive typography is a good example of something many of us have relied on media queries for. The fact that media queries come with their own CSS units — e.g., vw, vh, and so on — that are relative to the viewport size makes media queries look really good for adjusting font size based on the user’s screen size.
This works until that same component is moved into a different context, like a sidebar, where the viewport is completely irrelevant. Now, because we tied the responsiveness to the wrong reference point, the scaled typography can get too big or too small.
Container queries come with their very own units — cqi, cqw, cqb, among others — and we can take responsive components further by coupling those units with the CSS clamp() function, using it for fluid typography that scales with the component rather than the viewport:
Interestingly, container queries can, in a way, detect the state of a component’s internal layout. It’s not bulletproof, but it is also something media queries simply cannot do because they only observe the external browser window and are structurally blind to internal layout events like when, for example, flex items wrap onto a new line. Let’s poke at that.
Flexbox is superb at wrapping content (flex-wrap: wrap), allowing flex items to automatically wrap to new lines when the flex container runs out of space to fit them in a single row. But CSS by itself can’t tell when that wrap happens. There isn’t something like a :wrapped pseudo-class or a media query like @media (flex-wrapped: true) that would get us there.
Media queries only observe the browser window, as they can’t see internal changes. That is pretty much what flex wrapping is: a width state change on the item itself.
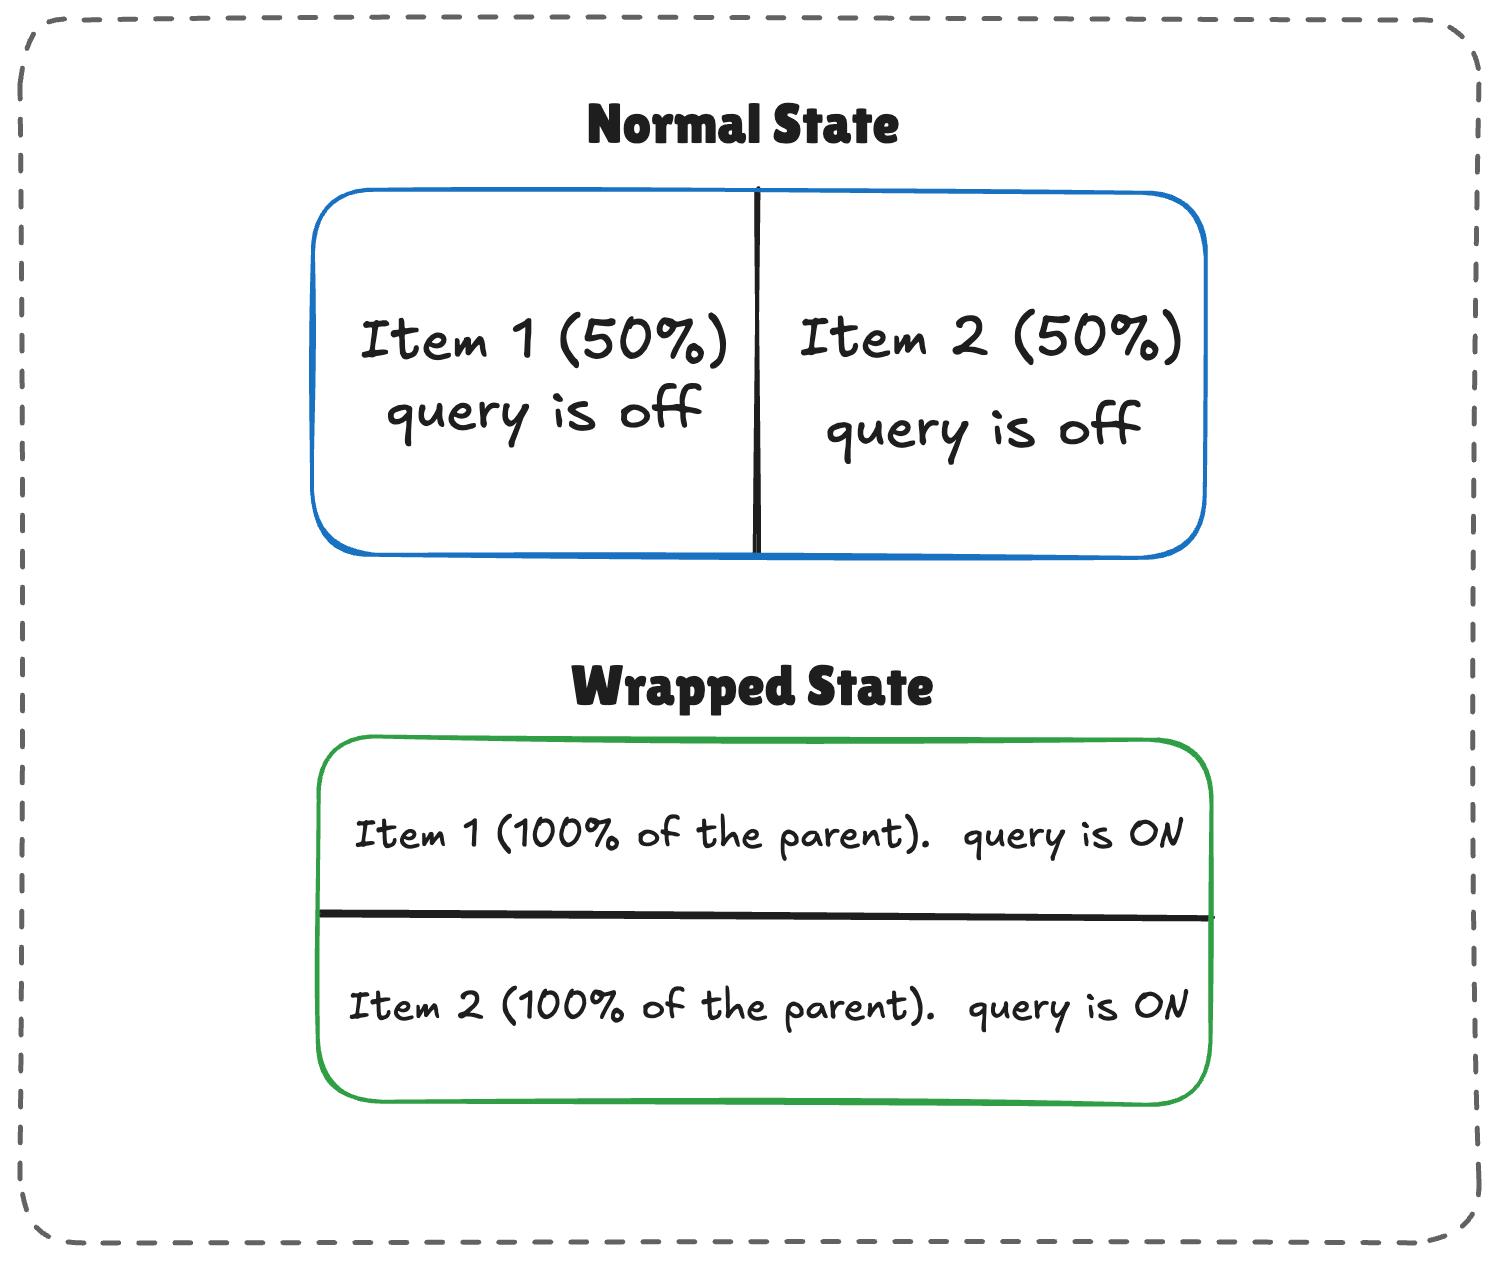
For example, if you have a horizontal menu that is lined up with flexbox and you want the items to restyle themselves only when wrapped, you’d be in JavaScript territory, using ResizeObserver to get that information. However, when we nest container queries inside flex items, we can come up with a workaround to get what we need without JavaScript, thanks to this technique I learned from Kevin Powell. The core idea is to allow a flex item to flex-grow: 1 when we query the container’s inline size.
When there’s enough room, both items (.flex-item) sit side-by-side, each exactly half the parent container’s width.
When there is limited space, the second item wraps to the next line.
Because flex-grow is active on each item, the wrapped items stretch to fill most of the parent’s width.
If the item is a container itself, it detects the sudden width expansion and fires.
/* The flex parent */.flex-layout{display: flex;flex-wrap: wrap;}/* Register a flex item as a container */.flex-item{container-type: inline-size;flex: 1 1 390px;/* Grow to fill space, wrap at 390px */}/* Default Card Styles (narrow / side-by-side) */.card{display: flex;flex-direction: column;background: #f4f4f4;}/* Once there's enough room for a full row */@container(min-width: 600px){.card{flex-direction: row;align-items: center;background: #e2f0d9;}}
This works. As the parent size shrinks and the cards wrap to two lines, the card item expands, the container query fires, and applies the necessary styles.
We can’t actually query the .card component to adjust the .card-content, like this:
/* DOES NOT WORK */.card{container-name: card;container-type: inline-size;}@container card (min-width: 400px){.card{display: flex;}}
This doesn’t work because a container cannot query itself. In that last example, we’re querying a card container and then attempting to adjust that container’s display based on its size. It’s an infinite loop.
Instead, we need an additional wrapper that makes the .card a descendant of the container:
In media queries, this doesn’t matter as @media does not care which element you style inside the block; its only concern is the viewport, which is always available. So you can just slap a condition on any element and call it a day.
2. Querying A Container’s size Could Collapse Your Layout #
This happens when querying the container’s size (i.e., its block, or vertical, size) instead of its inline-size:
/* Collapses to 0px even if it has content inside */.hero-banner{container-type: size;}
Why? Because the browser calculates the container’s dimensions without looking at its children. If we don’t give the .hero-banner an explicit height (or min-height or aspect-ratio), the browser sets a height of 0px.
For that reason, it’s often better to query a container by its inline-size instead. That is, unless you genuinely need to query the container’s block size.
Media queries aren’t affected by this, as they treat height the same way they treat @media (min-height: ...) does, i.e., ask the viewport and move on.
Another container query limitation: we can’t query against a custom property value:
:root{--breakpoint-lg: 1600px;}/* DOES NOT WORK */@container(min-width:var(--breakpoint-lg)){/* ... */}
This is because custom properties depend on values that cascade down the DOM tree. There’s the possibility that a container query that relies on a custom property can change that same custom property. And it can quickly get complicated:
:root{--breakpoint-lg: 1600px;}/* DOES NOT WORK */@container cards (min-width:var(--breakpoint-lg)){.card{--breakpoint-lg: 1000px;}}
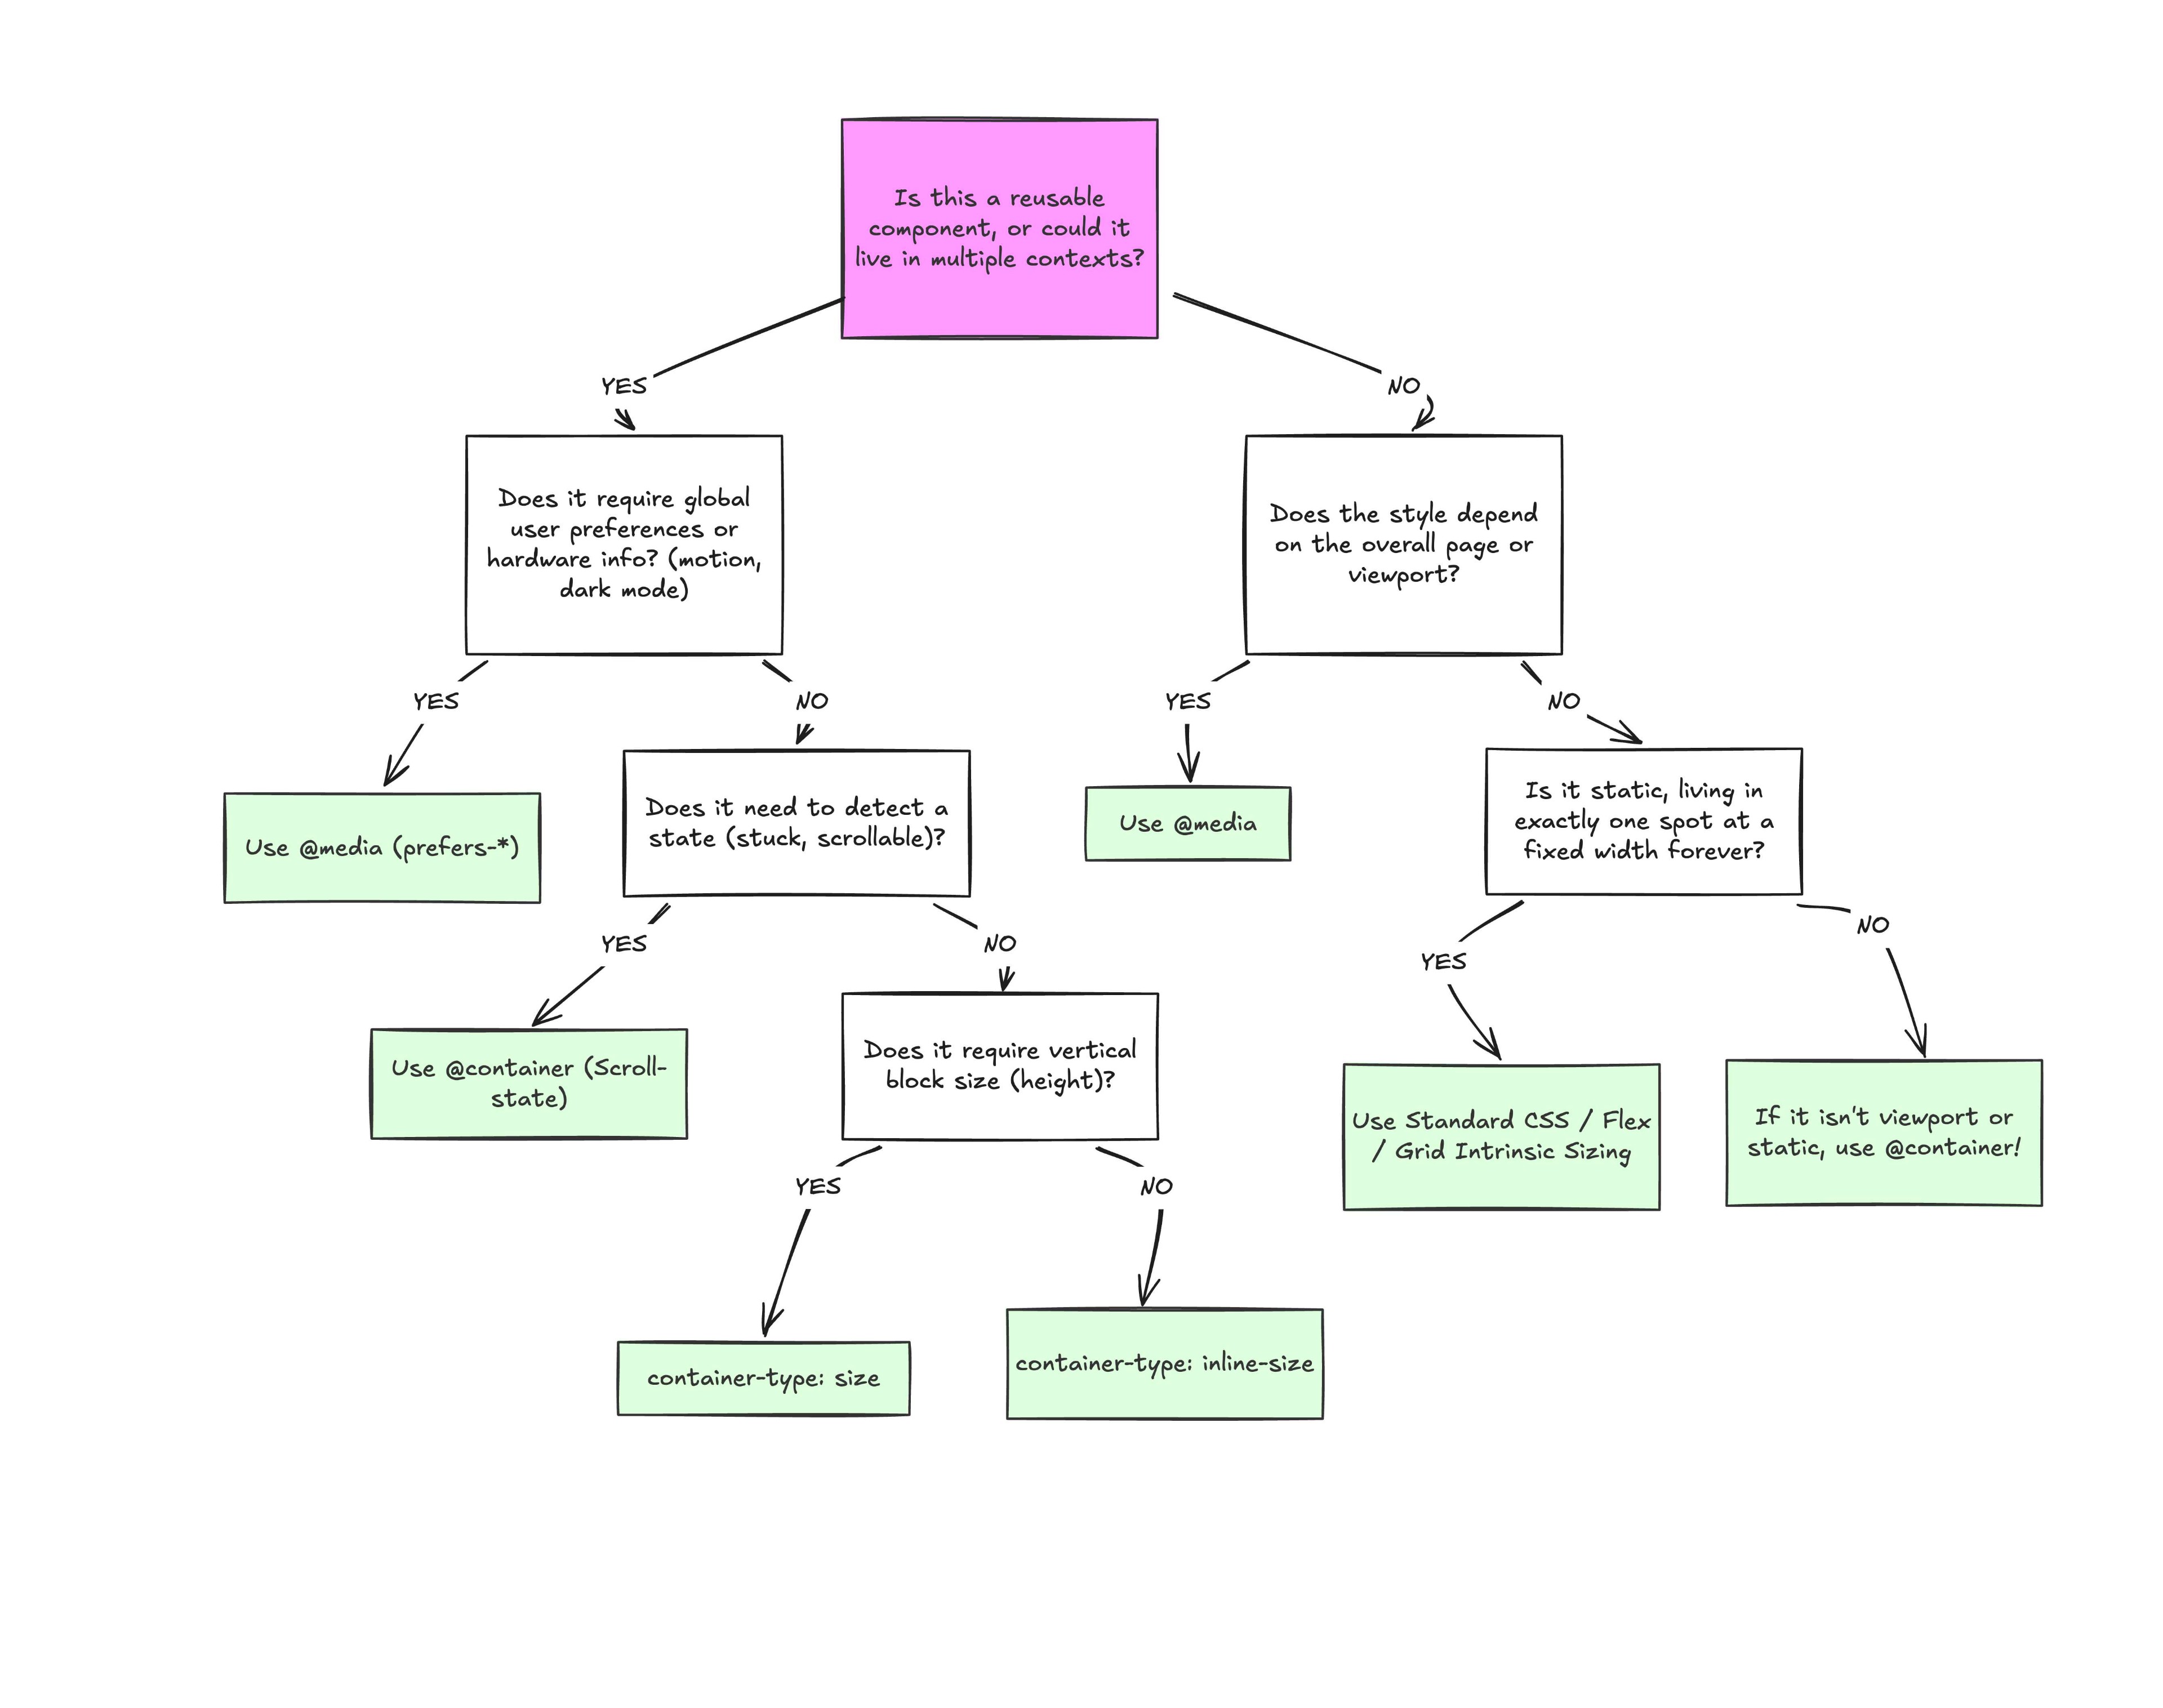
I don’t think any project should wholesale use @container instead of @media. Media queries still play an important role in responsive layouts. It’s about understanding the separation of concerns.
I tend to reach for container queries when a component is used in more than one layout context. For example, a .card element could live in a full-width grid or a narrower sidebar. If that’s the case, then we’ll want the component’s content to determine when it adjusts rather than a media query that looks at the outer viewport.
Similarly, I reach for media queries when a component solely exists at the page level. This would be something like a main navigation that always sits at the top of the page. It is directly influenced by the viewport’s size, meaning that the viewport is a reliable reference for when the navigation needs to adjust. Again, it’s all about “macro” layout versus “micro” layouts.
Here’s a diagram for how I reason about which type of query to use:
At the end of the day, the core reason why container queries look incredibly similar to media queries is simply familiarity. They’re not exactly “new”, but they are way less understood and adopted than media queries. But media queries have plenty of their own limitations; otherwise, we wouldn’t need container queries to fill those gaps.
What we have is a more effective feature for detecting when a specific component’s context changes and a means for adjusting styles based on its content, as it should be when that component can exist in multiple contexts.
We’ve
fallen into conversational tunnel vision, defaulting every AI
capability into a chat-based interface simply because LLMs are trained
on dialogue data. But great UX is about matching modality to users’
context, intent, and cognitive load, so the interface adapts to the
user, not the other way around.
The design community
has entered a period of conversational tunnel vision. Because Large
Language Models (LLMs) are trained on dialogue, the industry has
collectively decided that the chat bubble is the natural home for every
AI capability. While the chat interface is a viable and powerful option
for many tasks, it is one tool in an expansive toolkit. UX and Product
teams must be intentional about the modalities we choose for how users provide their data and commands, and how the system presents its output.
Modality is the way a person uses their senses to interact with a system: seeing, hearing, touching, speaking, or typing.
To
pick the best method, you need to think about what the user wants to
do, where they are, and how much cognitive effort they are already
expending. This guide offers a clear way to figure out the best approach
for any product, using two tools to assist in the process: a Task Audit
and an Input/Output Alignment Matrix.
Picture a traveler jogging
through a loud airport terminal after a sudden gate change. They are
dragging their roller bag and carrying a coffee in the other hand. They
need to open their airline app to ask the AI assistant where to go. The
tool immediately fails the input modality test. It forces the traveler
to stop walking, balance their coffee, and type a long booking reference
number into a tiny chat box. When they finally hit send, the system
fails the output modality test. Instead of flashing a large,
high-contrast gate number, the AI returns a dense paragraph explaining
the atmospheric weather patterns causing the delay. The actual gate
number sits buried at the very bottom.
While they might make the
flight just fine, the user won’t forget the moment of anxiety they felt
while using the AI tool — an experience that could have served as a way
to reinforce a commitment to UX has instead validated the common
conception that companies don’t care about or understand customers using
their products. In this scenario, the airline built a smart tool, but
the interface failed the user. The input required physical dexterity,
which the traveler lacked at the time of need. The output demanded a
level of reading focus they could not spare. This article will cover how
we can avoid this scenario in our AI-powered tools. In order to be
successful, we must evaluate the physical and cognitive load of our users to match both the input and output modality to their immediate intent.
Let’s first discuss the limitations of a chat-based interface.
Myth of the Do-It-All Chatbot
The
allure of the chatbot is easy to understand from a product development
standpoint. It is a blank slate. It suggests that the system can handle
anything the user provides. However, a text-heavy interface often causes
a high adaptation load. This load increases cognitive demands on users.
Over time, this cognitive burden turns into a psychological tax a
person pays when changing natural thought processes to accommodate a
machine.
When an interface relies solely on conversation, it imposes a dual burden: a linguistic challenge for input and a cognitive challenge for output. We’ll examine both separately below.
Input: Why a Text Box is a Linguistic Barrier
A
blank chat box creates a major problem for users who need to discover
what a tool can actually do. In a standard graphical interface, menus
and buttons provide clear visual cues that signal every available
option. A chat box often leads to choice paralysis
because users are forced to guess what the AI is capable of. They have
to remember the exact phrasing or technical terms required to get the
result they want.
Consider a data analyst who wants to find a
specific trend in a spreadsheet. In a traditional tool, they might click
a filter or sort button. In a chat interface, they must suddenly become
a writer and describe that complex logic in a complete sentence.
Another example: a manager trying to reorganize a team schedule.
Dragging and dropping blocks on a calendar is intuitive. Describing
those same scheduling shifts in a text prompt adds a layer of work that
makes the task feel more difficult than it should be.
Designing for input means recognizing that composing a prompt is a creative act.
It requires a person to translate a vague thought into a specific
command. For many professionals, this creates a linguistic barrier. A
designer might know exactly how they want an image to look but struggle
to describe the lighting or texture in a text prompt. In that case, a
slider or a color picker is a much better input method than a text box.
Having
addressed the linguistic barrier of constructing input prompts, we must
now consider the other half of the conversational burden. This is the
cognitive cost the AI imposes when it responds in dense blocks of text.
Output: The Cognitive Cost of Reading Long Text
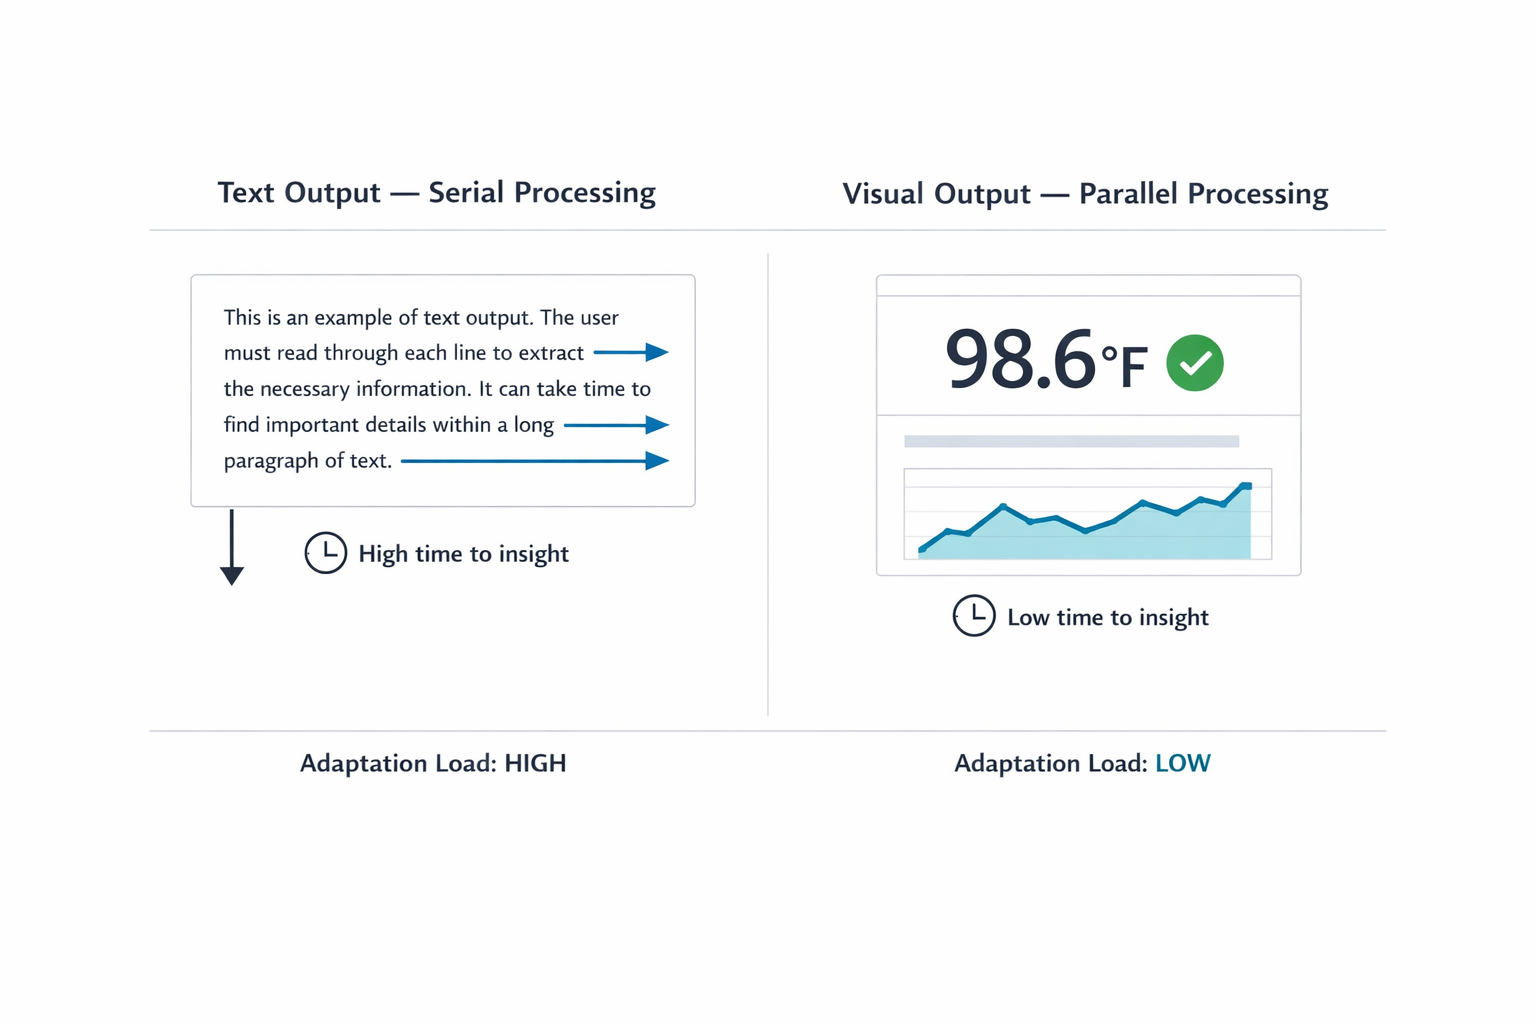
When an AI responds in long blocks of text, it transfers the interpretive work to you, the user. Text is a serial medium:
your brain has to read one word after the next to extract meaning. That
takes time. Sequential reading is necessary in many scenarios. Complex
legal analysis or reviewing nuanced medical histories requires reading
full paragraphs. Teams create friction when they default to text for
data that visual formats communicate faster. Visual methods allow
parallel processing. You can view a chart and spot a pattern in under a
second.
Imagine asking an AI for a project status update. Instead
of a color-coded dashboard, you receive three paragraphs listing every
task completed that week. Now you must read the entire response and
mentally summarize it to find the one piece of information you needed.
The quick visual check has been replaced by a reading assignment.
The cognitive tax
of this work compounds with professional stakes. A doctor asking for a
patient’s vital signs needs a clear numerical display, not a narrative
describing the readings. A stock trader looking for a price spike needs a
line graph immediately, not a written description of price movement
over the past hour. In both cases, a text response forces the
professional through a slow, error-prone extraction process when speed and accuracy are most important.
Figure
1: Redesigning for psychological fatigue. The linear text loop (left)
forces exhausting sequential verification, causing anxiety. The
graphical selection grid (right) permits instant, low-effort visual
confirmation (glance verification).
A Taxonomy of Input and Output Modalities
Before selecting a modality, practitioners need a shared vocabulary
for what the options actually are. The table below maps common input
and output modalities to the contexts where each performs best. This is
not a ranking. Each modality has a role; the question is always which role it is playing in a given workflow.
Designing for modality inherently requires a strong focus on accessibility.
While visual dashboards provide rapid insight for many people,
designers need to provide screen-reader-optimized audio alternatives for
users with visual disabilities. Modality choices should multiply
pathways to information.
Input Modalities
Modality
Best For
Example Contexts
Cognitive & Physical Rationale
Button / Tap
Single-step, binary actions
Launching a feature; confirming an alert
Eliminates recall overhead by utilizing recognition; maximizes execution speed during time-sensitive tasks.
Voice
Hands-busy or eyes-busy contexts
Field technician query; driving navigation
Offloads physical interaction to speech, though bounded by ambient noise and social privacy norms.
Natural Language Chat
Ambiguous or exploratory queries
Researching options; asking follow-up questions
Offers users freedom in what they can say; however, the user must figure out how to phrase their request clearly.
Form / Wizard
Structured, multi-field data entry
Filling out a contract; configuring a report
Keeps users from missing information by breaking down a complicated task into clear, step-by-step visual sections.
GUI (Filters, Sliders, Drag-and-drop)
Complex parameter setting or spatial tasks
Scheduling; data filtering; image editing
Prevents mistakes and ensures users don't miss information by dividing complicated tasks into clear, step-by-step visual parts.
Multi-modal (Image + Text)
Visual input paired with description
Uploading a design mockup with annotation
Reduces the effort of explaining things because users can reference an object instead of having to describe it only with words.
Gesture
Hands-free spatial interaction
Waving a hand to acknowledge an alert in a sterile operating room
Allows
physical interaction without touching a surface. This keeps users safe
and clean in contaminated environments and allows for quick input or
acknowledgement.
Output Modalities
Modality
Best For
Example Contexts
Cognitive & Physical Rationale
Push Notification / Alert
Time-sensitive, ambient awareness
Price spike alert; task completion notice
Provides
a quick update that the user can process at a glance. It delivers
information without demanding a full break in concentration from their
primary task.
Audio Summary
Hands-busy or eyes-busy contexts
Status updates while walking; conversational voice agents providing real-time navigation
Delivers
information directly to the user’s ear. Removes the need to look at a
screen, keeping the user safe and aware of their physical surroundings
while moving or working.
Short Text Summary
Focused queries needing brief answers
Definition lookup; single-metric status
Gives
a fast answer to a direct question. Users can read a short sentence
quickly without experiencing the fatigue of scanning paragraphs of text.
Visual Dashboard
High-density, comparative analysis
Project status; resource allocation
Enables
visual trend and outlier detection. Avoids the mental effort of reading
data line-by-line and cross-referencing in real time.
Interactive Canvas
Generative or iterative creative tasks
Design iteration; layout adjustment
Allows
users to manipulate the output instead of asking an AI to move it via
text instructions. Reflects a natural way to interact with the output.
Inline Confirmation
Guided task flows needing feedback
Step-by-step configuration wizard with in-line validation
Provides visual proof that the system recorded a choice correctly. Reduces users’ anxiety about wondering if an error occurred.
Table 1:Input
and Output Modality Taxonomy. Use this as a reference during the Task
Audit to identify candidate modalities before narrowing to a
recommendation.
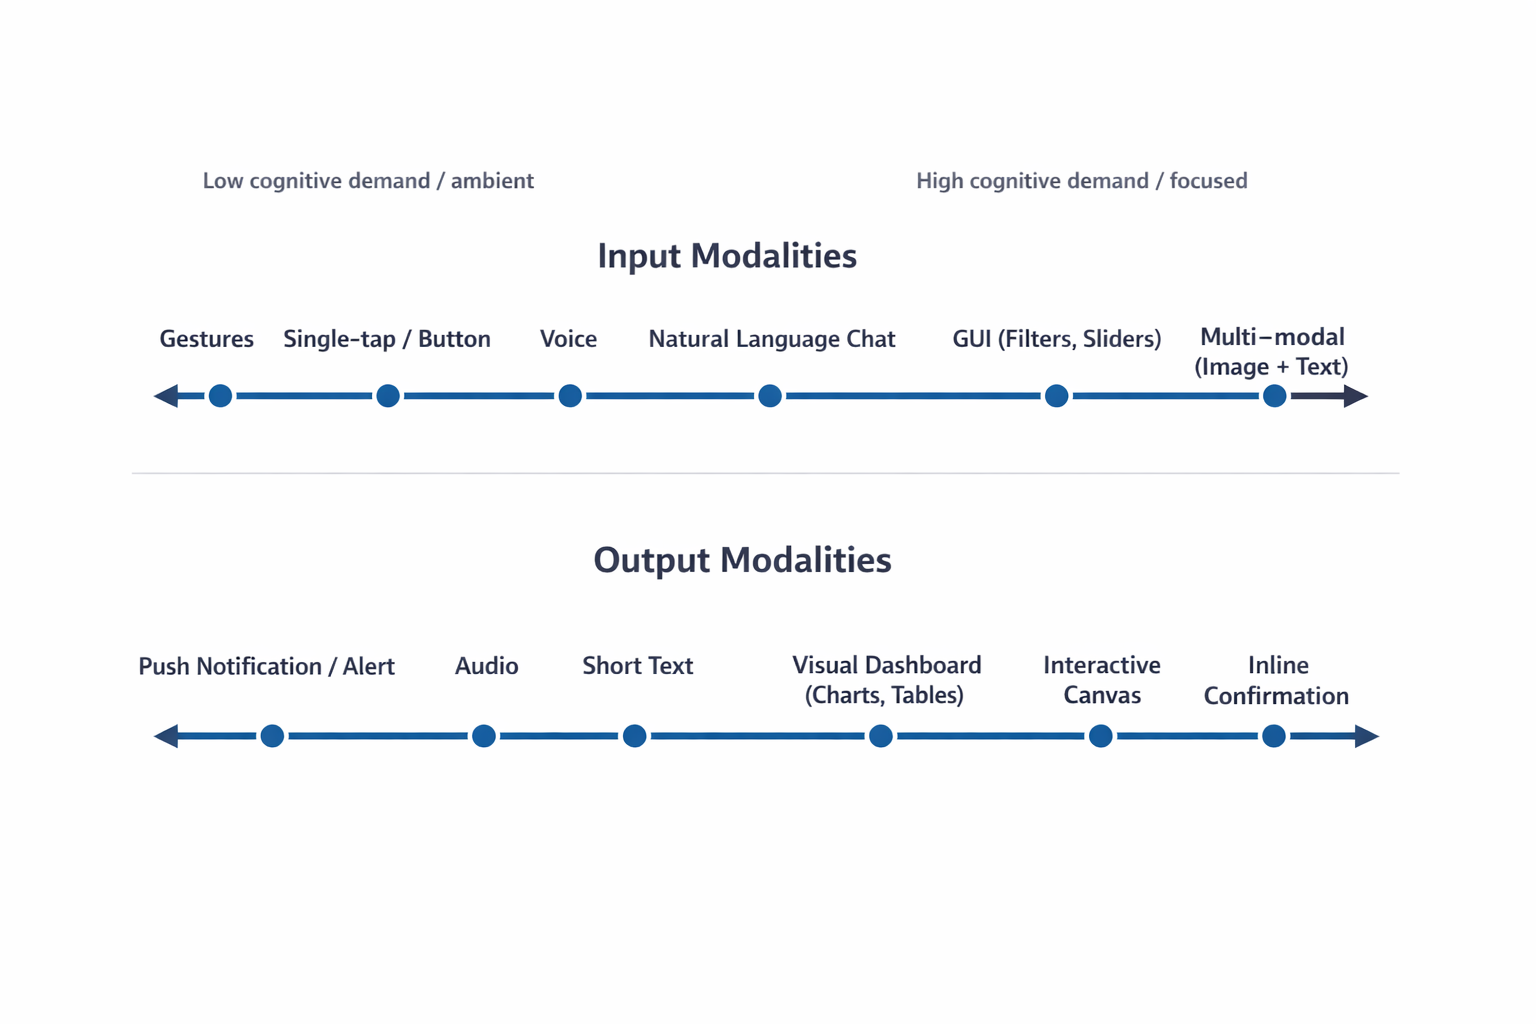
The following FigureFigure 2 illustrates the cognitive spectrum,
mapping how mental effort scales across various interaction methods.
This spectrum is a critical tool for designers to visualize the shift
from low-effort, ambient interactions to high-effort, focused
experiences. By understanding where a specific task sits on this
spectrum, teams can identify whether a user needs a “glanceable” output
that minimizes mental processing or a high-density format that supports
deep, analytical thinking.
Figure
2: The Cognitive Spectrum of Modality. Both input (top) and output
(bottom) move from low-effort, ambient interactions to high-effort,
focused, and multi-modal experiences, illustrating why the context of
use must dictate the design choice.
With
this taxonomy established, the next step is to apply a rigorous method
to select the optimal input and output combination. Practitioners must
ground this selection process in the user’s real-world environment and
context.
Task Audit: A Framework for Modality Selection
To choose the right interaction method, practitioners should complete a Task Audit before interface design begins. A formal Task Audit is the framework that moves teams from assumptions about user behavior to evidence.
This process gathers data about the physical, social, and cognitive
context in which the work actually happens, which then drives all input
and output modality decisions.
Use these four areas of focus to anchor the audit:
Input Constraints:
This addresses whether the user can physically interact with the system
using their hands, such as typing or tapping. It often dictates the
necessity of hands-free interaction methods like voice input when the
user’s hands are occupied by tools or gear.
Can the user use
their hands to type or tap? A mechanic working under a vehicle might
need to ask a question using only voice because their hands are occupied
and covered in grease.
Output Constraints:
This defines whether a user can safely and practically view information
on a screen. It concerns situations where a user’s eyes must remain
focused on their environment, making audio or glanceable visual cues the
appropriate display method.
Can the user safely look at a screen
to read information? A delivery driver’s navigation system should
provide audio directions because reading a detailed map while driving
through an intersection is dangerous.
Social Constraints:
This considers the environment’s tolerance for audible interaction,
either speaking or listening to audio output. It helps determine if a
quiet space requires silent alerts or if a loud environment demands a
non-audio output method.
Is the environment appropriate for
speaking aloud or listening to audio? An office worker in a quiet,
open-plan space would prefer a silent text notification over a spoken
voice response.
Cognitive Load: This
measures the amount of mental effort the user must already dedicate to
their primary task. Teams must design the interface output to either
minimize mental processing, such as with a quick visual indicator, or
support deep thinking with a detailed summary.
How much mental
effort does the task already require? A surgeon needs a quick visual red
indicator during a procedure, while a lawyer researching case strategy
needs a detailed text summary to absorb at their own pace.
The audit answers two questions for every feature:
What modality can the user physically use to provide input here?
What modality can the user realistically process as output here?
Here is how to gather the evidence to inform your task audit. Use one or more of these common UX research-related methods:
1. Contextual Inquiry and Observation
This is the most direct way to capture how people work in their natural setting,
and it provides the richest data for identifying physical constraints
on both input and output. Observation is necessary because users often
perform hidden work: small steps or workarounds they forget to mention
in an interview, or environmental details they do not think to describe
because they have adapted to them.
The Approach: Go to the user’s actual workspace, whether a
field site, warehouse, or office floor. Ask them to perform the task you
are studying and observe closely.
What to Look For: This method is most revealing for Input Constraints and Output Constraints.
Input example A technician diagnosing equipment who cannot put down their tools rules out typing and points directly to voice input.
Output example A
supervisor in a meeting who looks up and down repeatedly from a screen
signals a need for glanceable, low-density output rather than a
scrolling text summary.
2. Focused Interviews
Interviews
surface the mental models and decision points that observation cannot
capture. They are most valuable for understanding Cognitive Load.
The Approach:
Conduct one-on-one sessions with end-users and the stakeholders who
manage the outcome. Use a structured protocol focused on a specific
task. Ask for stories about past successes and failures rather than
general opinions.
What to Look For:
The “Why” Behind High Cognitive Load Ask
users to describe the hardest part of a task. A lawyer may explain that
the volume of detail is not the challenge; synthesis for ethical or
strategic judgment is. This confirms a need for detailed text output the
user can read and absorb at their own pace, not a summary dashboard.
Process Ambiguity Uncover
situations that are unclear or error-prone, which identifies where AI
capabilities provide the most leverage and what output format will
reduce rather than increase ambiguity.
3. Collaborative Workshops
Workshops
are essential for defining task boundaries and establishing required
fidelity levels. Product managers and stakeholders bring foundational
knowledge of system requirements; researchers apply audit criteria.
The Approach: Use workshops to build a shared Task Inventory.
Bring designers, engineers, product managers, and business analysts
together to map every step of the process. Product managers and business
analysts ensure factual accuracy; the research team applies audit
criteria to each step.
What to Look For:
Social Constraints Confirm
where tasks are performed. A workflow that takes place on a loud
manufacturing floor versus a shared quiet library demands very different
output modalities.
Ambiguity and Speed Tests For every task in the inventory, apply two tests. First: Does this step require human ethical judgment? If yes, the AI output must support that judgment, not replace it. Second: Does this step require instantaneous execution? If yes, the interface must support fast input with minimal cognitive overhead.
Once you gather field evidence through these research channels, map your findings directly against the Modality Taxonomy.
Each concrete physical or social constraint you document systematically
eliminates mismatched interfaces. This process strips away design
guesswork, narrowing your architectural choices down to the specific
input and output combinations that survive the reality of the user’s
environment.
When you ground input and output modality decisions
in field evidence rather than interface convention, the resulting design
reduces adaptation load for the user and grounds your modality choices
in evidence. When you base decisions on field data, you move past
interface convention and build a powerful case for the resources needed
to create the right experience for your users.
Once the audit is
complete, the final step is utilizing the Input/Output Alignment Matrix
to formalize the connection between user intent and the optimal modality
combination.
Input/Output Alignment Matrix
With Task Audit findings in hand, you can use an Input/Output Alignment Matrix
to map user intent to specific modality combinations. This matrix is
organized by what the user is trying to accomplish in a given moment.
This distinction versus focusing on what your AI is capable of doing
matters. If intent changes across a single workday for the same user,
the interface should respond to those shifts.
Choosing the wrong
modality for the user’s context can lead to user frustration. Users
might feel mentally drained if a lot of information is delivered through
a format that is hard to process, like getting a massive status update
only in text. They may also start worrying if an action was actually
completed correctly when a precise command is buried within a long chat
exchange. Finally, the system can force users into finding clumsy
workarounds, making them adapt to the machine’s method instead of
working in their natural, most effective way.
User Intent
Optimal Input Modality
Optimal Output Modality
Environmental Fit
Quick Status Check
Voice or Single-tap Button
Audio or Push Notification
Hands-busy, Eyes-busy (e.g., Technician on ladder)
Specific Detail Query
Natural Language Chat
Short Text Summary
Focused, low-density data need
Complex Analysis
GUI (Filters, Sliders)
Visual Dashboard (Charts, Tables)
Desk-based, high-resolution screen
Creative Generation
Multi-modal (Image + Text)
Interactive Canvas
Design or drafting environment
Monitoring / Alert
Passive (background system)
Push Notification or Audio Alert
Any environment; task is ambient awareness
Guided Task Completion
Structured Form or Step-by-step Wizard
Inline Confirmation + Progress Indicator
Focused workflow; user needs verification feedback
Table 2:Input/Output
Alignment Matrix. Map user intent to modality combinations using Task
Audit evidence. The two added rows (Monitoring/Alert and Guided Task
Completion) cover common enterprise and mobile scenarios not captured in
simpler frameworks.
When teams coordinate these factors,
they can move past the automatic default of adding a chatbot. Visual
layouts enable rapid scanning. Structured inputs remove the burden of
constructing perfect sentences. Audio outputs serve users whose hands
and eyes are otherwise occupied.
The right modality combination respects the user’s physical and cognitive state at the moment of interaction.
A
real-world scenario where environmental constraints dictated a shift in
design strategy best demonstrates the practical application of this
matrix and the broader audit framework.
Case Study: Adaptive Modality for Field Technicians
The Problem: Cognitive Overload in High-Risk Environments
Field
technicians servicing high-voltage electrical grids often face a
dangerous misalignment of interface modality. Traditionally, these
technicians had to rely on ruggedized tablets to access technical
manuals and log status updates. However, the physical constraints of the
job — wearing heavy protective gloves and working in bucket trucks at
significant heights — made interacting with a standard touch interface
nearly impossible while on a job site. Additionally, attempting to read
complex, text-heavy diagnostic reports on a screen while maintaining
situational awareness created a high cognitive load that increased the
risk of safety errors.
Research Methods: Capturing the Reality of the Field
To address this, researchers conducted a Task Audit utilizing three specific methods from this article. First, Contextual Inquiry and Observation
revealed that technicians often worked in “hands-busy, eyes-busy”
states where any manual input was a significant barrier. Researchers
observed technicians wearing mandatory thick protective gloves while in
the bucket truck, which made precise screen taps nearly impossible and
often triggered the wrong commands.
High-altitude environments
also introduced severe screen glare from direct sunlight, washing out
the display and making text difficult to read even at full brightness.
Furthermore, technicians faced the physical safety risk of trying to
manipulate and secure a heavy, ruggedized tablet while balanced in
awkward positions, creating a distraction that could lead to dangerous
slips or equipment contact. These factors, combined with the need to
constantly monitor live wires and the surrounding environment, meant
technicians could not safely dedicate their eyes or hands to a standard
tablet interface, confirming the severity of the eyes-busy and
hands-busy constraints.
Second, Focused Interviews with
veteran technicians validated the findings from the field. They
confirmed that the operational challenges, including the thick gloves,
screen glare, and safety risks, were not unique to one location but were
commonly experienced across multiple sites, including high-altitude
transmission lines and sprawling power substations. This broad
confirmation solidified the need for a non-touch, voice-first solution.
The interviews also surfaced a critical cognitive constraint: the need
for glance verification of vital signs, such as voltage readings and
temperature trends, rather than being forced to read a long narrative
description of system health. Technicians stressed that their primary
need was immediate, unambiguous verification (is this safe? or where is
the fault?), not a lengthy diagnostic report, indicating that a
text-heavy response was dangerous to their workflow.
These methods
confirmed that the environment required a departure from the
traditional chat or form-based AI capability interface.
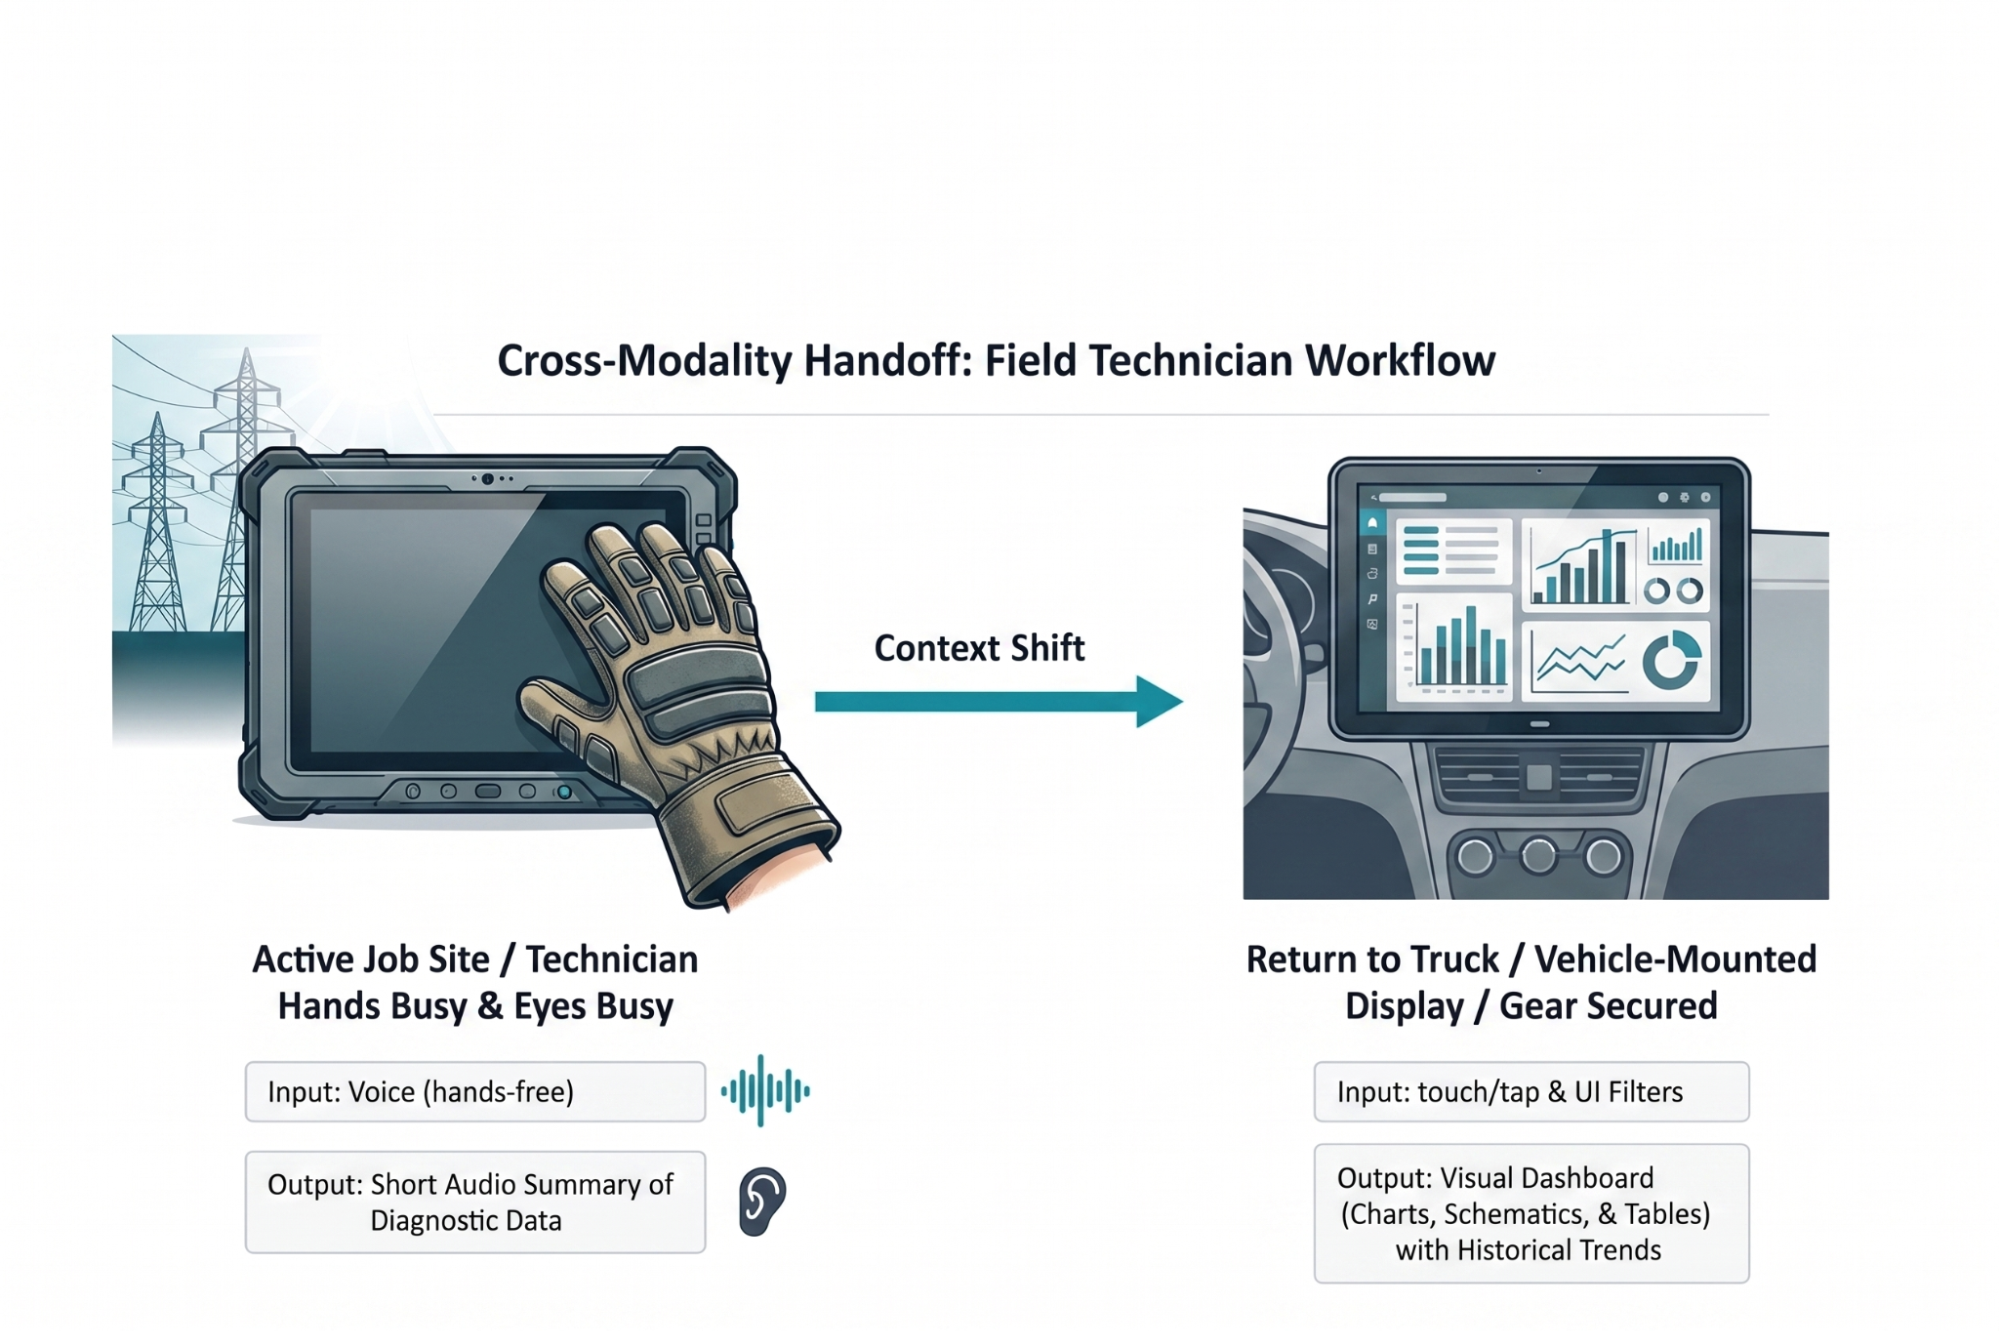
The Resolution: A Multi-Modal Handoff Solution
The
resulting solution implemented an adaptive modality handoff designed to
mitigate the physical and cognitive barriers researchers identified
during the research. While active on a job site, technicians utilize
voice input to query the system. This method allows them to remain
productive while wearing thick protective gloves that would otherwise
prevent precise interaction with a touchscreen.
The AI responds
with a short audio summary of immediate diagnostic data. This audio
feedback bypasses the challenge of screen glare in high-altitude
environments and allows the technician to maintain situational awareness
of the high-voltage grid without the safety risk of looking away from
dangerous equipment. By providing immediate answers to fault locations
through audio, the system meets the technician’s need for glance
verification through a hands-free and eyes-free channel.
Once
technicians return to a truck and secure safety gear, a system
automatically hands off workflows to a 15-inch visual dashboard mounted
inside a vehicle. A rugged 10-inch field tablet lacks adequate screen
real estate for complex schematics. A larger vehicle display allows for
parallel processing of historical trend data and wide electrical grid
maps. This case study reflects an actual field audit conducted for a
national utility provider. Implementing this adaptive approach reduced
diagnostic time by twenty percent and increased daily tool adoption
among field crews.
Figure
3: Cross-modality handoff diagram for field technicians. Our solution
to deliver AI capability using multiple modalities depending on context
was the result of auditing user tasks and led to greater adoption of the
tool.
Designing for the Environment
An
AI capability is only as usable as the interface that delivers it.
Researchers and designers must resist the pull toward the path of least
resistance. Building a chatbot is fast and familiar, something we’ve
been doing for decades now. Building an interface that feels like a
natural extension of how someone already works is harder, and it is the
work that matters.
Start by leaving the screen. The Task Audit
requires presence in the places where work actually happens: the field
site, the warehouse floor, the operating room. The physical and social
realities of those spaces are not edge cases. They are the design brief.
The
future of AI interface design is a diverse ecosystem: visual, vocal,
haptic, and ambient, calibrated to user intent and environmental
context. The chat window is one tool in that ecosystem. It is the right
tool for specific jobs, and often the wrong tool for the jobs we
reflexively assign to it.
In order for us to create the
greatest likelihood of acceptance and use of the AI capability we offer
users, we must fit the modality to the person and the place.
Where to Start
To
get started immediately, run a lightweight version of the Task Audit
before your next design sprint. Spend two hours observing the workflow
in its actual environment. Conduct three to five interviews with the
people who perform the task. Bring a PM or analyst into a 90-minute
workshop to build a task inventory and apply the four audit questions.
You will not have complete data, but you will have enough to make a
defensible modality recommendation backed by evidence rather than
convention.
I created a Modality Task Audit Template to help guide
teams with moving forward. You can download this worksheet and take it
directly to your next field observation. It allows design and product
teams to document specific physical barriers before writing a single
line of code.
Step 1: Physical Reality Check. An observation checklist to log hand availability, eye focus requirements, and ambient noise levels in a specific workspace.
Step 2: Cognitive Baseline. A scoring grid to rate required reading density and verification anxiety for a given workflow.
Step 3: The Handoff Map. A
blank flow diagram to chart where a user starts a task (for example,
using voice on a mobile phone in a warehouse) and where they finish it
(for example, reviewing a visual dashboard on an office monitor).
We
focus heavily on training smarter AI models. We owe equal attention to
human interfaces. A brilliant underlying model packaged in a lazy text
interface fails. When you observe actual work environments and align
interaction modalities to them, you remove adaptation friction.
Modality Task Audit Field Template
Use this worksheet during field observations. It allows design teams to document specific physical barriers before writing code.
Part 1: Physical Reality Check
Observe users as they perform a primary task in actual workspaces. Check all applicable conditions.
State of Hands
Visual Focus Requirements
Ambient Noise Level
Part 2: Cognitive Baseline
Rate the mental effort required to complete a specific workflow.
Teams
can generate UI faster than ever, but they still have to guarantee that
what they ship is usable, secure, and maintainable. Accessibility as an
operational capability rather than a compliance checklist or
end-of-project audit, and what that looks like in practice.
This article has been kindly supported by our dear friends at Level Access,
who help organizations create accessible and legally compliant
websites, mobile apps, software, and other digital experiences. Thank you!
We
know that right now, a senior engineer is shipping a checkout flow they
“built” in a single afternoon. AI assistant does the heavy lifting,
happy path runs clean, and a rotating chevron spins on the order
summary. Two weeks later, engineering gets a notice from customer
support: a blind customer using a screen reader can’t complete the
purchase because the “Pay Now” control is a <div> with a click handler. No role. Not focusable. Not working.
That
gap — between code that runs and a product people can actually use — is
becoming one of the defining engineering challenges of the AI era.
Teams can generate UI faster than ever, but they still have to guarantee
that what they ship is usable, secure, and maintainable.
Accessibility sits right in the middle of that problem.
This
is not an article about compliance checklists or end-of-project audits.
It’s about engineering systems. Specifically, why accessibility should
be treated as an operational capability — alongside privacy, security,
reliability, and observability — and what that looks like in practice.
The Audit Trap
For
years, the default way to “do” accessibility was the one-time,
audit-only approach: hire a firm, get a list of 200 findings, fix some
of them, file the report. A lot of teams have now moved beyond this
model — and the reason is worth looking into.
Audits do matter. For sales, procurement, governance — they’re essential. When a buyer asks for a VPAT or an ACR, you need one. When legal asks if you’re meeting requirements, you need documentation. Audits serve those purposes well.
But
audits don’t help you build accessible features during sprint planning.
Audits can cost points during a sprint. They don’t catch problems
before merge requests. They don’t scale with deployment velocity.
The mistake, essentially, is tackling accessibility as a snapshot when
you really need constant monitoring. Six months after the audit, the
product has shipped dozens of releases, multiple new features, and a
redesigned nav. The report is now fiction. Compliance is not a state you
reach — it’s a state you maintain, and complexity fights you the whole
way.
The WebAIM Million report,
which scans the top one million home pages every year, found that 95.9%
of pages had detectable WCAG failures in its 2026 run, with an average
of 56.1 errors per page. The number of page elements jumped more than
20% in a single year, likely driven by AI-enabled development and ‘vibe
coding’ — and more elements mean more places to break. Accessibility
debt behaves exactly like technical debt: every inaccessible component
you ship becomes a future remediation project, and the interest
compounds.
Any strategy that treats accessibility as a periodic event rather than a continuous property of the system is going to lose.
The AI Problem Nobody Wants To Name
With the scale at which teams now generate UI, the gap doesn’t just persist; it multiplies.
Start with how fast this arrived. In February 2025, Andrej Karpathy coined “vibe coding”
— a way of working where you “fully give in to the vibes” and “forget
that the code even exists”. You describe intent, the model generates,
you accept the diffs without reading them. It was meant for weekend
projects. It did not stay there. Y Combinator reported that 25% of its Winter 2025 batch had codebases that were 95% AI-generated.
Models
don’t land on non-semantic markup by accident — three forces push them
there. Most React code on GitHub uses non-semantic “soup”, so that’s
what the models learn. Human reviewers and evaluators judge output
visually, so the feedback loop rewards looks, not semantics. And <div onClick> is fewer tokens than <button aria-expanded="true" ...>, so absent a constraint, the model takes the cheap path.
Here’s
the thing about AI-generated UI: it’s inaccessible by default. Not
occasionally — by default. A developer writing in Frontend Masters tested AI-generated React components across multiple tools and documented the pattern.
A typical AI-generated sidebar had ten distinct accessibility failures
in twenty-nine lines: no landmark, no heading, no list structure,
elements with click handlers instead of buttons, no aria-expanded, no
keyboard handling, and unlabeled icons. The accessibility tree — the
structure screen readers actually read — came back as flat, unstructured
text. “Same pixels” as the author put it. “One is a door. The other is a
painting of a door”.
Now connect this to security, because the two failures come from the same root. Veracode’s 2025 GenAI Code Security Report
tested large language models across dozens of coding tasks and found
that a large fraction of AI-generated code introduced security
vulnerabilities — including OWASP Top 10 flaws. Cross-site scripting
failures were particularly common, and security performance did not
meaningfully improve with newer, larger models. The issue wasn’t model
intelligence. It was process: developers generating code without
specifying security constraints and accepting output without systematic
verification.
The same shortcut that skips the security review
skips the accessibility review. At scale, AI won’t close the
accessibility gap — it has industrialized the very thing that creates
it.
The fix is not to ban AI. Your developers are already using
it. The fix is to constrain it and verify it — to treat AI as a very
fast teammate who always needs guardrails.
This is usually where someone says, “Guardrails? Sounds great, but they will slow us down.”
In practice, the opposite tends to be true.
Shift-left
is the entire DevOps thesis, and it applies cleanly here. An
accessibility issue caught during design review is a comment. The same
issue found in production is a remediation project.
Catching an
accessibility issue as a component is built takes minutes. Fixing one
after the fact — discovering it in an audit, diagnosing the root cause,
restructuring the markup, applying the necessary fix, writing tests —
can easily take hours. Multiply that across hundreds of findings from a
late-stage audit, and you have weeks of unplanned work that earlier
automated checks — whether in design reviews, development workflows, or
CI — could have prevented.
Teams that integrate accessibility into
everyday workflows avoid the expensive surprises: emergency audits,
remediation sprints, procurement blockers, and redesigns that quietly
break core user journeys. Accessibility doesn’t reduce velocity.
Unexpected work reduces velocity. In-flow accessibility is one way of
eliminating unexpected work.
What Enterprise-Ready Actually Looks Like
The organizations that scale accessibility successfully do not rely on heroes. They rely on systems.
The highest-leverage place to start is the design system. One accessible component can be reused thousands of times. The GOV.UK Design System
is a useful example: components undergo both automated and manual
testing using assistive technologies such as JAWS, NVDA, VoiceOver, and
TalkBack. The team is explicit about the limits of automation and
supplements tooling with user testing involving people with
disabilities. They’re equally clear that using the design system doesn’t
“magically” make a service accessible; it just gives you a higher
starting point.
Accessibility becomes infrastructure. That’s the lesson.
From there, it moves into the engineering workflow:
Accessibility requirements are included in the Definition of Done.
Pull request reviews include explicit accessibility checks.
Interactive controls use semantic elements (<button>, <a>) by default.
Keyboard navigation and focus management are treated as standard engineering concerns, not optional polish.
Finally, accessibility becomes enforceable through automation:
At that point, accessibility stops depending on memory and starts depending on the process. It becomes part of your platform.
Patterns That Actually Scale
A few implementation patterns consistently show up in teams that do this well.
Constrain AI Before It Generates
Instead
of fixing accessibility after generation, bake requirements directly
into tooling through Cursor rules, Copilot instructions, or
repository-level standards. Tell the model to use semantic HTML. Tell it
when to use buttons versus links. Tell it to expose the state and
labels correctly. Models follow persistent constraints far more reliably
than one-off prompts.
Stop Hand-Rolling Complex Widgets
Comboboxes,
menus, tabs, modals, and similar controls routinely become
accessibility hotspots. Libraries such as Radix UI, React Aria, and
Headless UI already solve many of these problems. The scalable approach
is not about repeatedly implementing accessibility correctly. It’s
inheriting accessible behavior from well-tested primitives.
Capture Accessibility During Design Handoff
Focus
order, labels, heading hierarchy, and interaction states should be
specified before implementation begins. If accessibility requirements
are absent from the design artifact, they are often absent from the
final product. A simple memo at design handoff — what is the tab order,
what are the labels, what happens on error — removes a huge amount of
guesswork later.
None of these patterns is exotic. They’re just DevOps and platform thinking applied to accessibility.
The Broader Business Impact
Engineering
leaders rarely prioritize accessibility solely because of regulations.
But regulations, procurement requirements, user retention, and product
quality all point in the same direction.
Legal pressure continues to increase. Digital accessibility lawsuits in the United States have stayed in the thousands per year, and they are not limited to large enterprises. The European Accessibility Act
is now enforceable across the EU, applying to e‑commerce, banking,
ticketing, telecoms, and more, regardless of where the company is
headquartered. The message is clear: accessibility is no longer a
“nice-to-have” in the eyes of regulators.
But compliance is only part of the story. The bigger story is the market you leave on the table. The World Economic Forum (December 2023)
estimates that the world’s 1.3 billion people with disabilities, “along
with their friends and family, has a spending power of $13 trillion”;
disabled consumers alone control roughly $8 trillion in annual
disposable income, per the Valuable 500.
In the UK alone, the Click-Away Pound Report 2019
found the “Click-Away Pound has risen to £17.1 billion” — more than 4.9
million users with access needs who abandon inaccessible sites and
spend elsewhere, up almost 45% from £11.75 billion in 2016. People don’t
file a bug report. They leave and buy from a competitor.
There is
also a procurement reality that turns accessibility from a cost into a
moat. If you sell B2B or to government, you will increasingly be asked
for proof of accessibility — VPATs/ACRs or equivalent documentation.
According to Level Access’s Seventh Annual State of Digital Accessibility Report,
75% of organizations now require proof of accessibility at least most
of the time when purchasing digital products — essentially unchanged
from 74% in the previous report, but with a notable shift towards
stricter enforcement, as those that always require it rose from 27% to
31%. A strong ACR accelerates the sales cycle; a weak one, or none at
all, creates redlines that stall or kill it. For some buyers, this is a
hard requirement before your product can even enter evaluation. A strong
accessibility story accelerates the sales cycle. A weak one creates
redlines that stall or kill it.
Step back and the deeper pattern
is clear: accessibility is a proxy for engineering maturity. A team that
ships semantic HTML, manages focus, exposes state correctly, and tests
it in CI is a team that has its house in order. The same discipline that
produces an accessible component produces a maintainable, testable,
less buggy one.
For dev and product leaders, that’s the real
business case: accessibility work is platform work. It pays off every
time a feature ships faster and more smoothly, with less rework, than it
otherwise would have.
Systems, Not Sprints
If
you take one thing from this, make it this: accessibility doesn’t come
from an audit, a hero, or a heroic remediation sprint before launch. It
comes from systems.
An accessible design system so components
start right. A Definition of Done so they stay right. Automated testing
and CI gates so regressions fail the build. Governance, so someone owns
it. Guardrails for AI-assisted development so your fastest tool stops
being your biggest liability.
None of those practices is
particularly glamorous. That’s exactly why they work. They’re the same
kinds of boring, reliable systems you already trust for security,
reliability, and performance.
But there’s one thing no tool on
that list can do. No linter, no automated scanner run, no dashboard will
ever tell you what it’s actually like to use your product as a blind
person with a screen reader, or to navigate your checkout with a
keyboard because a tremor makes a mouse inoperable.
So build the systems — you need them, and they’re the only way
accessibility survives contact with a real release schedule. But test
with real users with disabilities regularly. The first time you sit
behind someone using JAWS to fight through a form your team thought was
“done”, something changes. The tooling tells you whether you passed. A
real person tells you whether it actually works.
Accessibility is
not a feature. It’s an operational capability. Treat it that way, and
you get something dev and product leaders already care about: a faster,
safer, more reliable way to ship software.
A closer look at why users don’t need more tools in their daily lives.
What they need are seamless integrations of useful features to match
already existing, established mental models.
We often hear about shiny new tools that change everything (yet again). But in practice, most people don’t need more tools to deal with in their daily lives. What we actually need are better integrations of useful capabilities that neatly align with our existing and established mental models.
Users
don’t get excited about shiny new “smart” workflows, or navigating
Terminal commands, or jumping between endless back-and-forth chat
interactions. They need seamless integrations of useful features to address problems with high severity, high frequency, and a high level of frustration.
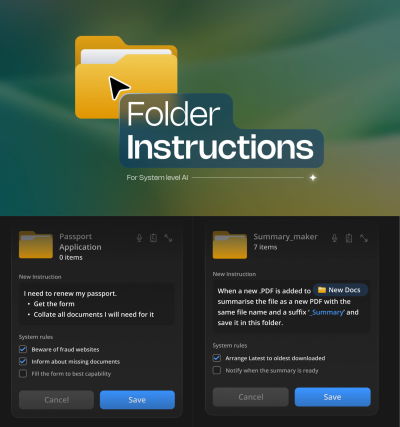
Now, that’s useful: seamless integration of AI features when creating new folders. By Karthikeya GS.
1. AI-First vs. Quiet AI
I’ve always been puzzled by the notion of “AI-first”
products. They might speed up production, but we need to know really
well first what we actually want to build. AI-first often doesn’t
account for years of small and big design decisions that have shaped expectations and mental models over the years.
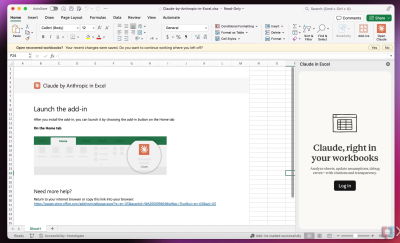
A neat Claude Excel integration, with users studying specific rows or columns, instead of switching between tools all the time.
I love the notion of “Quiet AI”.
These are tools that are mostly invisible, sit in the background, and
do small tasks on the user’s behalf. They never scream for attention but
happily assist in repetitive, frustrating tasks that can easily be
automated or assisted with a smart helper.
Excellent examples of Quiet AI include Claude’s integration within Microsoft Excel, PowerPoint, and Word, providing assistance in context without disrupting the user’s workflow.
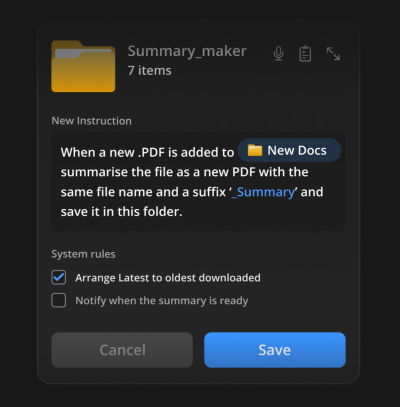
So no wonder that I absolutely love the idea of folder instructions!
There, users can define what a folder is supposed to do, based on the
purpose they created it for. It sounds much more complicated than it
actually is.
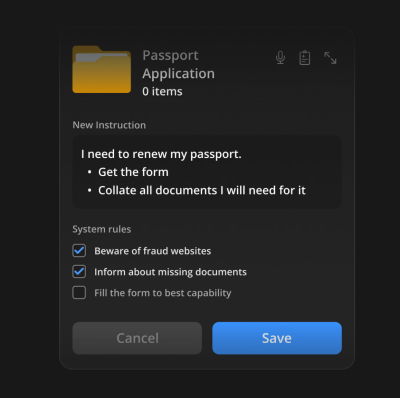
Users define instructions, choose system rules, and the system takes care of the task.
The instructions define what the folder is for, how files should be organized,
how sub-folders should behave, and what actions can happen inside.
Instead of manually maintaining a folder, you set its intent once and
let the system follow it.
It’s a seamless integration
of AI helpers just when and where users want and need it. With
permissions and actions locally scoped to that specific folder on the
user’s machine, unless the user extends access, permissions, or system
rules on their own.
Users could automate tasks where the work actually happens, e.g., generating summaries on the fly.
Here are some useful examples:
For a passport renewal,
get the form and collect all the documents I need for it. Inform about
missing documents, and fill out the form to the best of your abilities.
When new invoices
are added to the folder, rename them according to the sequence, sort
them by invoice number, and organize them in folders by client.
When a new PDF is added to the folder, generate a summary, send it to my pocket, and send me a notification via email.
User’s
value doesn’t emerge from users having to juggle between multiple
applications, views, and sources every few minutes. That’s when they are
slowed down, and that’s when they make mistakes.
It comes from helping users do the work they need to do — by reducing frustrations, slowdowns and mistakes, and taking care of tasks that otherwise would take too much time and too much effort to complete well.
Yet again, seamless integrations
— a very underused but incredibly impactful way to deliver value fast,
without adding the burden of installing and learning yet another tool.