Payment of ₹ requested by HONEY VIG. Click the link to pay securely via Razorpay: Make 5000 payment Payment of ₹ requested by HONEY VIG. Click the link to pay securely via Razorpay: Make 5000 payment ⭐ If you would like to buy me a coffee, well thank you very much that is mega kind! : https://www.buymeacoffee.com/honeyvig
Hire a web Developer and Designer to upgrade and boost your online presence with cutting edge Technologies
Showing posts with label Research. Show all posts

Monday, October 13, 2025

SerpApi: A Complete API For Fetching Search Engine Data

 From competitive SEO research and monitoring prices to training AI and parsing local geographic data, real-time search results power smarter apps. Tools like SerpApi make it easy to pull, customize, and integrate this data directly into your app or website.

SerpApi leverages the power of search engine giants, like Google, DuckDuckGo, Baidu, and more, to put together the most pertinent and accurate search result data for your users from the comfort of your app or website. It’s customizable, adaptable, and offers an easy integration into any project.

What do you want to put together?

  • Search information on a brand or business for SEO purposes;
  • Input data to train AI models, such as the Large Language Model, for a customer service chatbot;
  • Top news and websites to pick from for a subscriber newsletter;
  • Google Flights API: collect flight information for your travel app;
  • Price comparisons for the same product across different platforms;
  • Extra definitions and examples for words that can be offered along a language learning app.

The list goes on.

In other words, you get to leverage the most comprehensive source of data on the internet for any number of needs, from competitive SEO research and tracking news to parsing local geographic data and even completing personal background checks for employment.

Start With A Simple GET Request

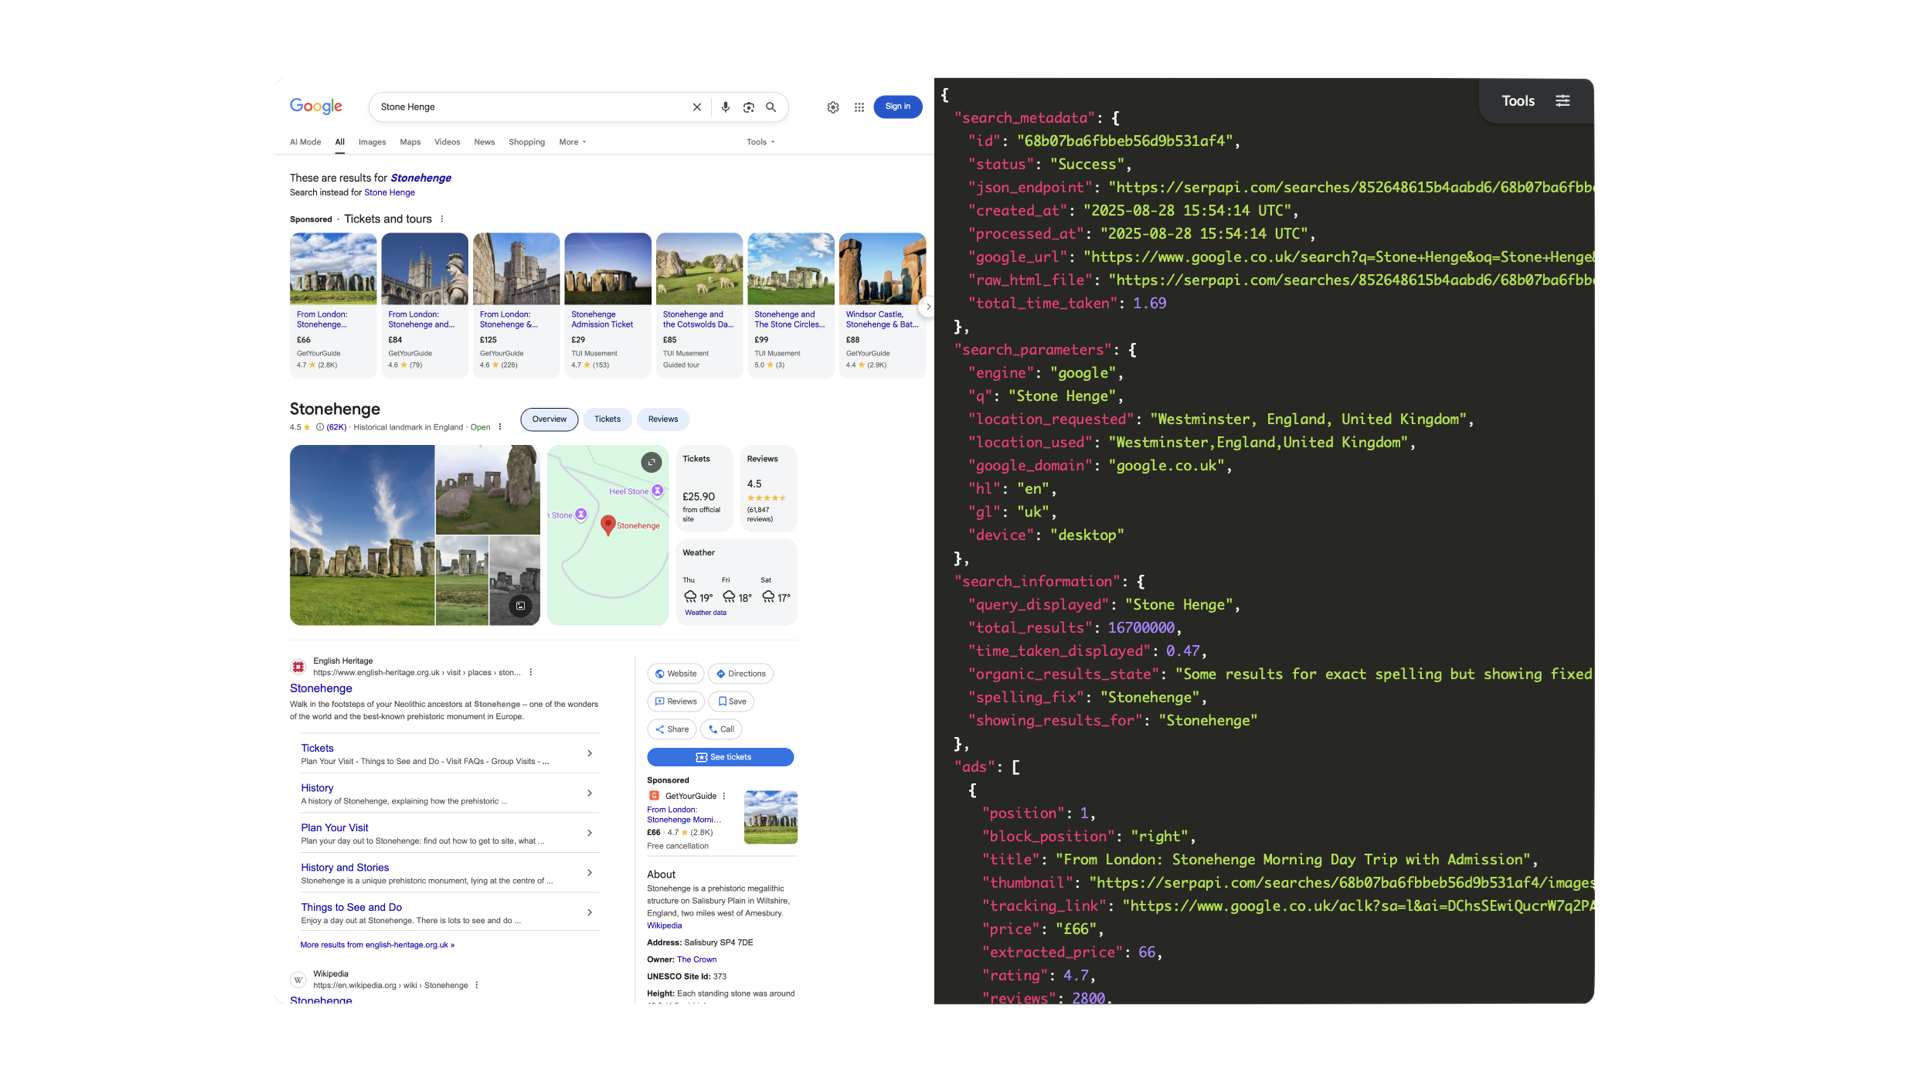
The results from the search API are only a URL request away for those who want a super quick start. Just add your search details in the URL parameters. Say you need the search result for “Stone Henge” from the location “Westminster, England, United Kingdom” in language “en-GB”, and country of search origin “uk” from the domain “google.co.uk”. Here’s how simple it is to put the GET request together:

https://serpapi.com/search.json?q=Stone+Henge&location=Westminster,+England,+United+Kingdom&hl=en-GB&gl=uk&google_domain=google.co.uk&api_key=your_api_key
(Large preview)

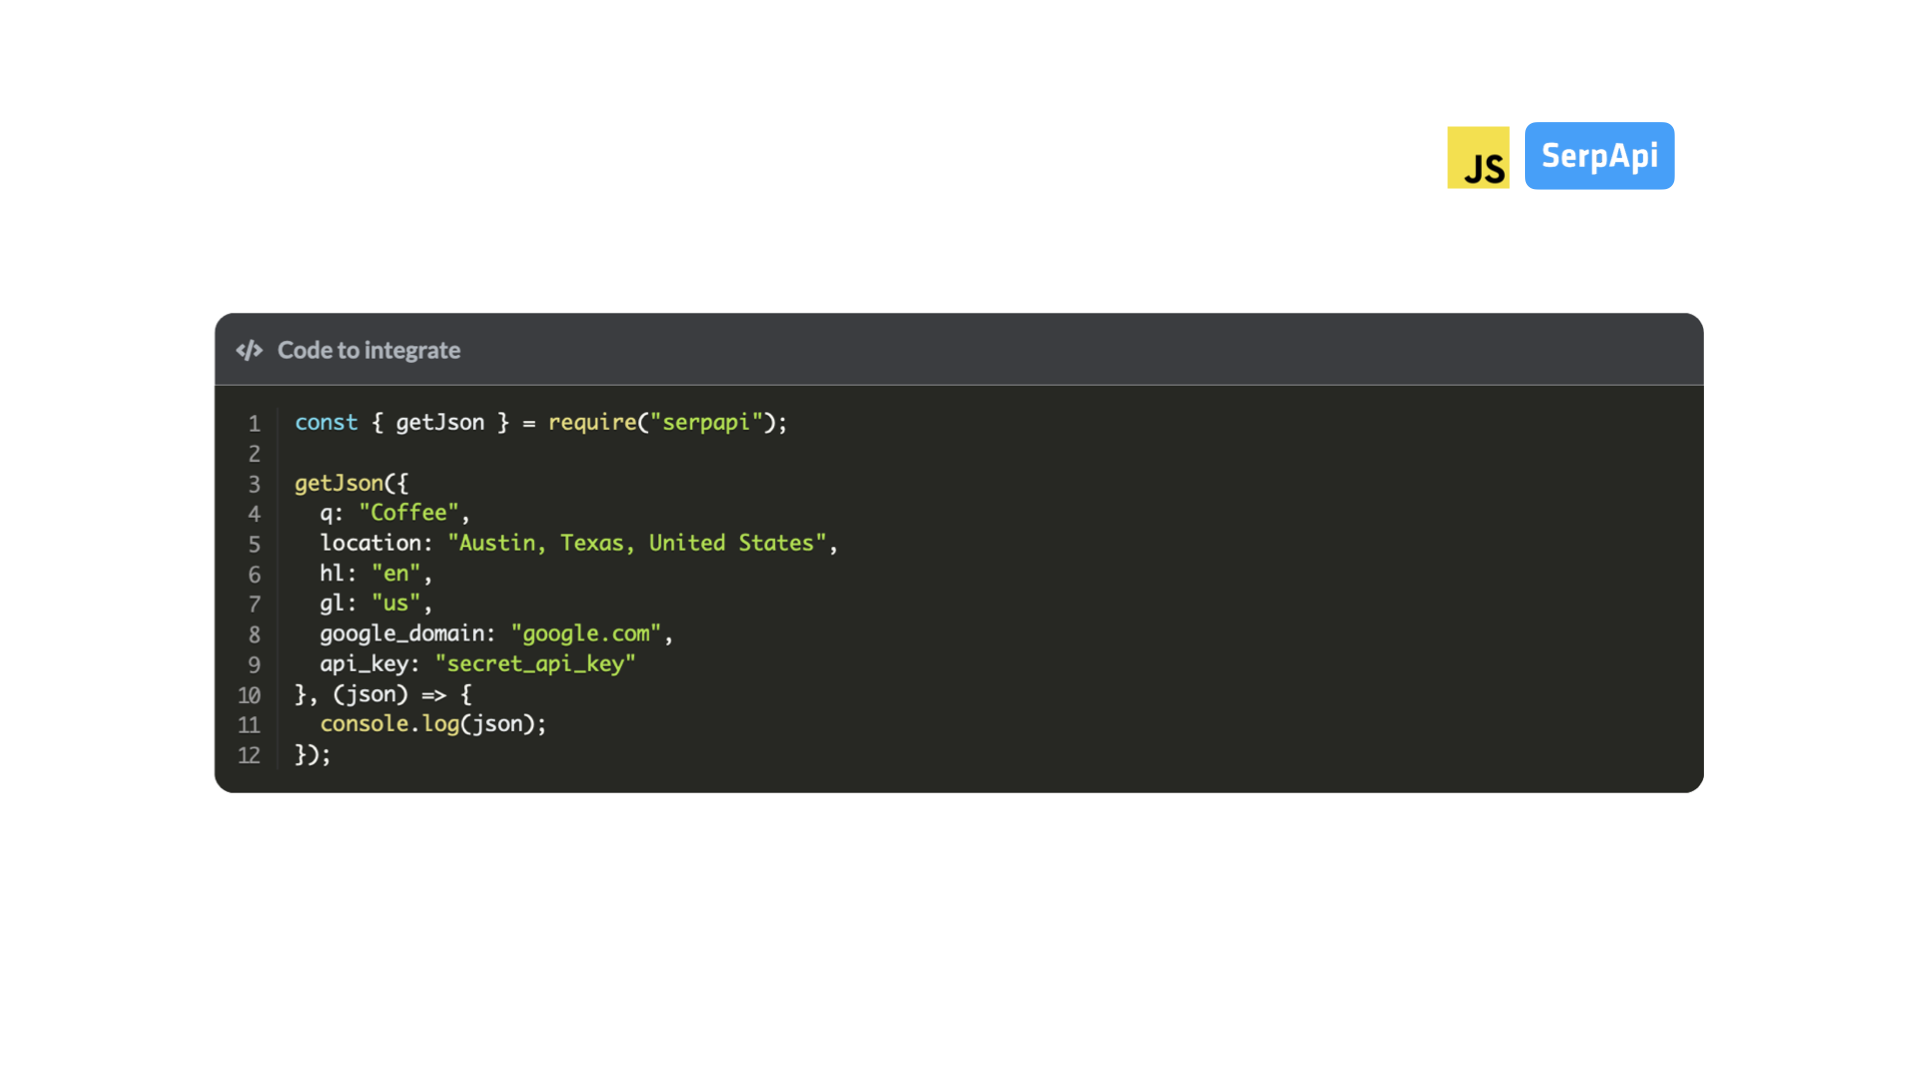
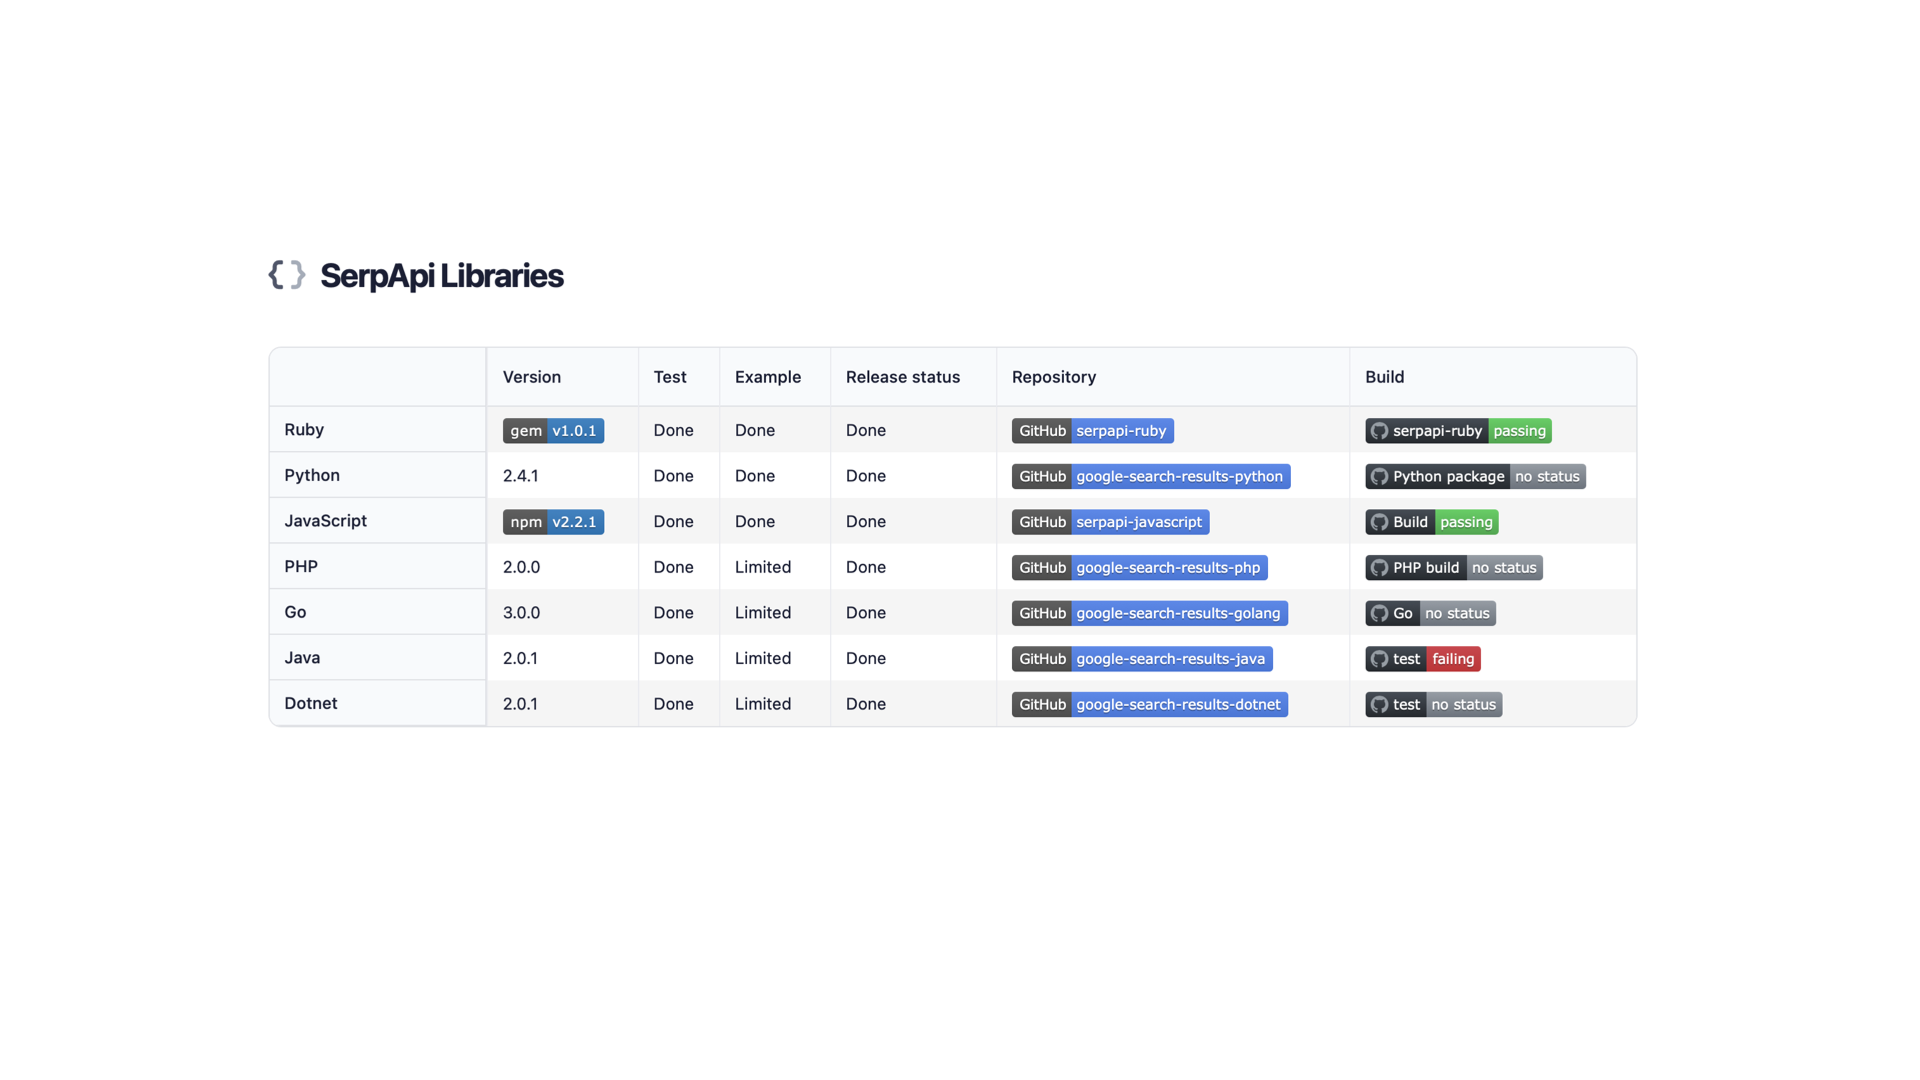
Then there’s the impressive list of libraries that seamlessly integrate the APIs into mainstream programming languages and frameworks such as JavaScript, Ruby, .NET, and more.

JavaScript integration code for SerpApi
JavaScript integration code for SerpApi. (Large preview)
Table of SerpApi libraries showing information about seven libraries.
(Large preview)

Give It A Quick Try #

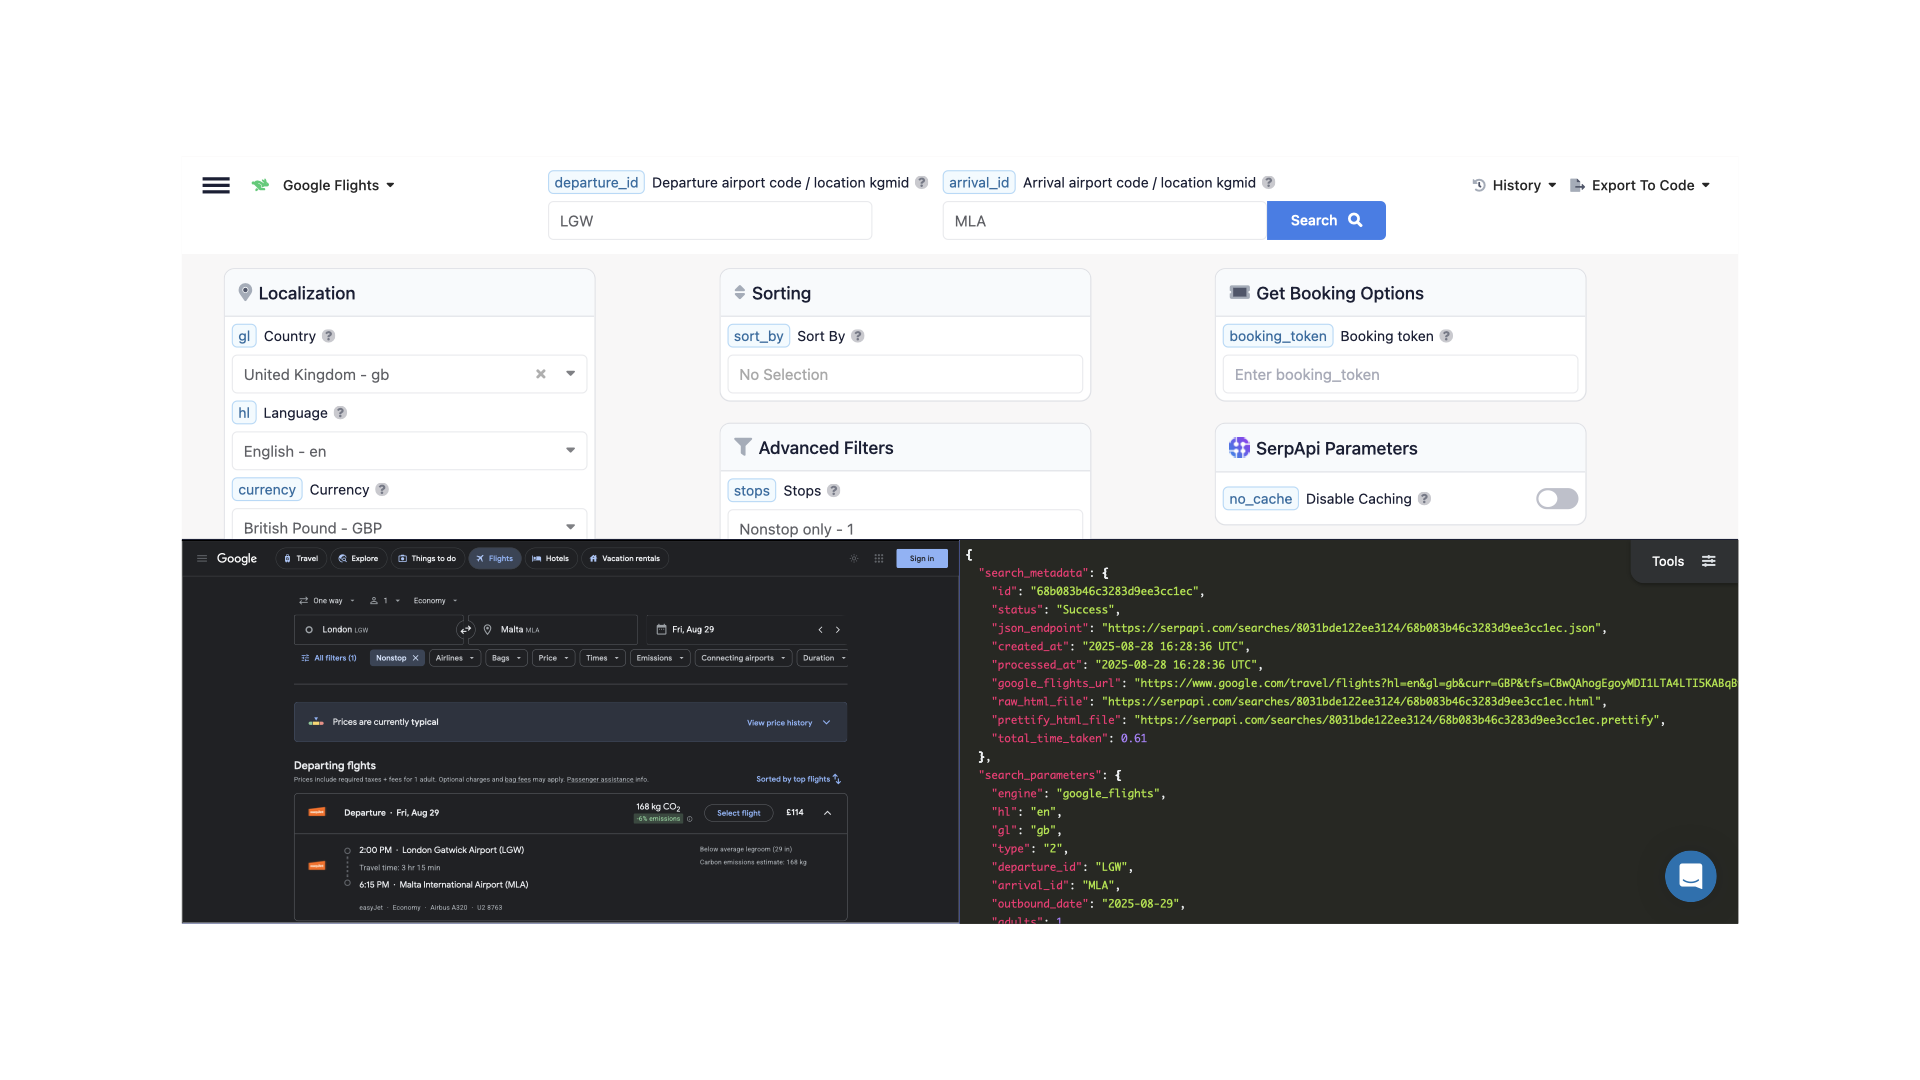
Want to give it a spin? Sign up and start for free, or tinker with the SerpApi’s live playground without signing up. The playground allows you to choose which search engine to target, and you can fill in the values for all the basic parameters available in the chosen API to customize your search. On clicking “Search”, you get the search result page and its extracted JSON data.

Playground search for flights from LGW to MLA airport using SerpApi’s Google Flights API.
Playground search for flights from LGW to MLA airport using SerpApi’s Google Flights API. (Large preview)

If you need to get a feel for the full API first, you can explore their easy-to-grasp web documentation before making any decision. You have the chance to work with all of the APIs to your satisfaction before committing to it, and when that time comes, SerpApi’s multiple price plans tackle anywhere between an economic few hundred searches a month and bulk queries fit for large corporations.

What Data Do You Need? #

Beyond the rudimentary search scraping, SerpApi provides a range of configurations, features, and additional APIs worth considering.

Geolocation #

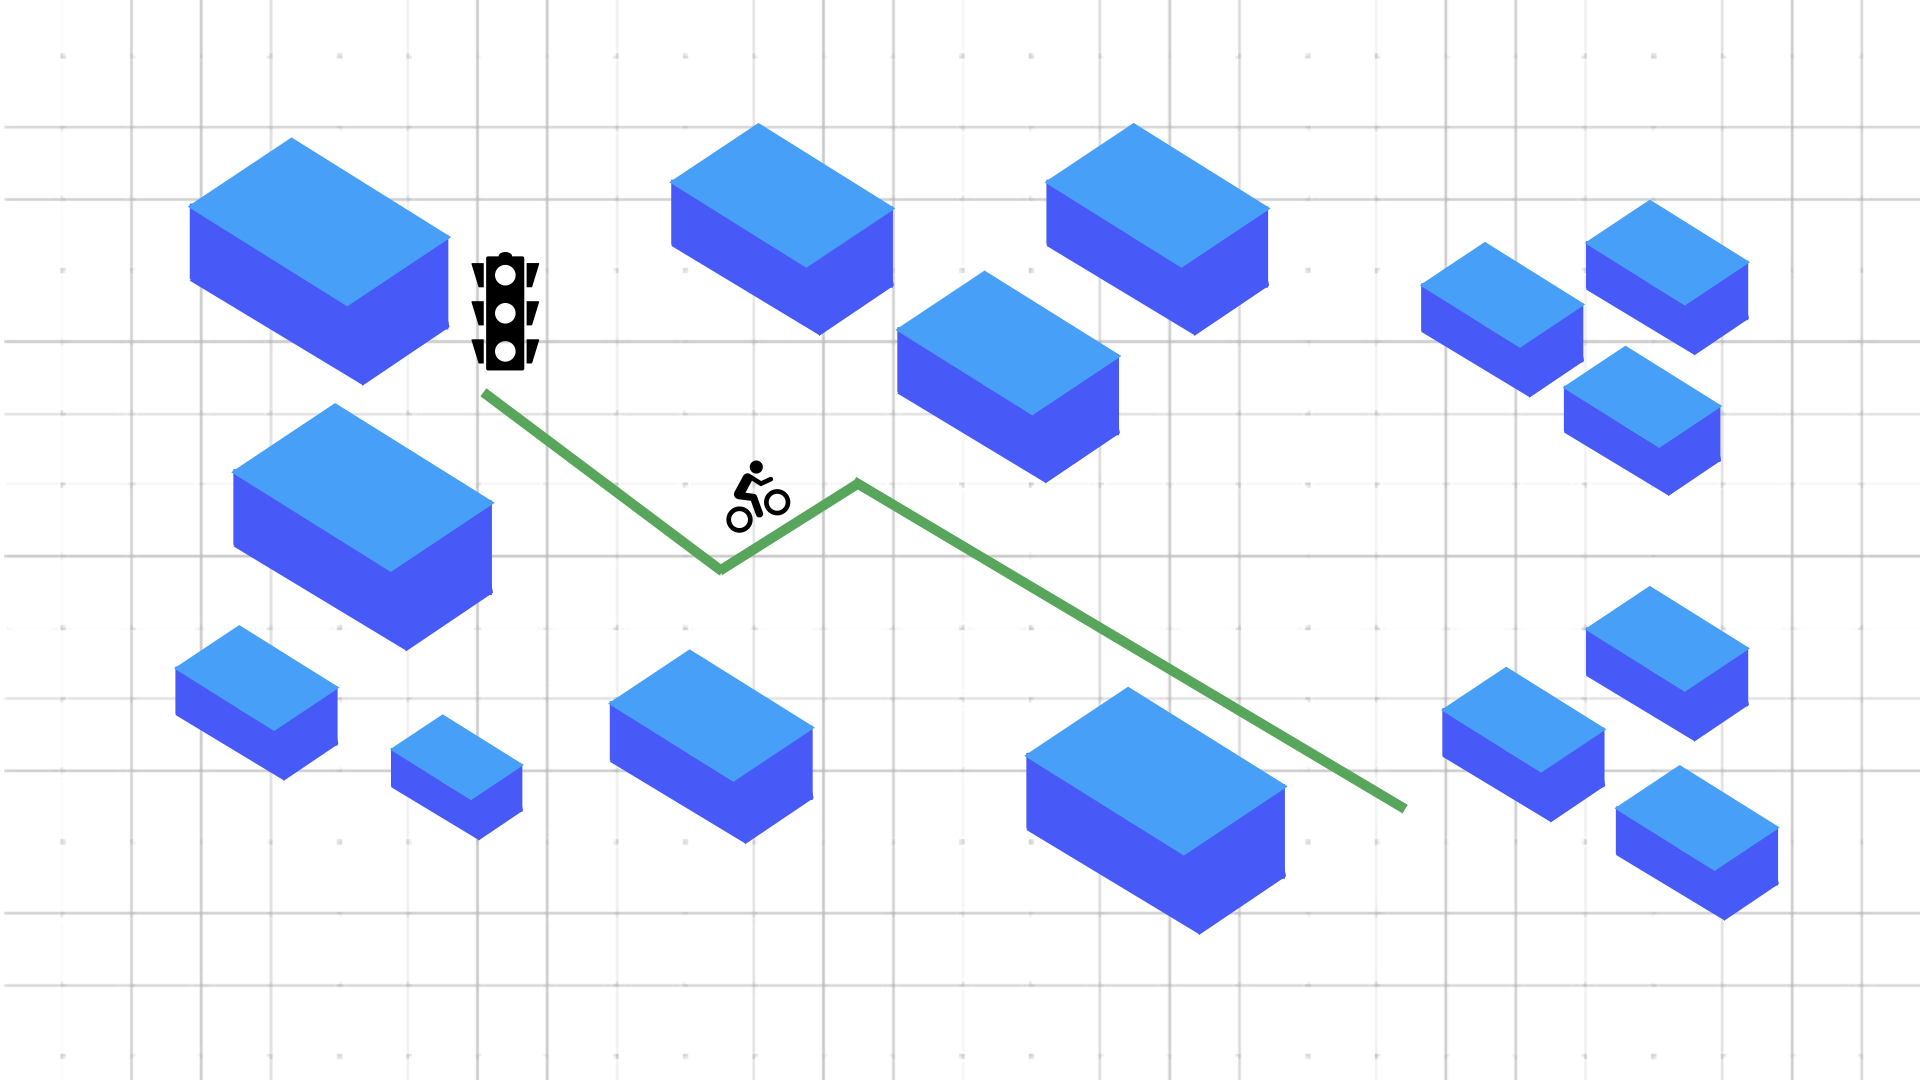
Capture the global trends, or refine down to more localized particulars by names of locations or Google’s place identifiers. SerpApi’s optimized routing of requests ensures accurate retrieval of search result data from any location worldwide. If locations themselves are the answers to your queries — say, a cycle trail to be suggested in a fitness app — those can be extracted and presented as maps using SerpApi’s Google Maps API.

SerpApi’s cycle route
(Large preview)

Structured JSON #

Although search engines reveal results in a tidy user interface, deriving data into your application could cause you to end up with a large data dump to be sifted through — but not if you’re using SerpApi.

SerpApi pulls data in a well-structured JSON format, even for the popular kinds of enriched search results, such as knowledge graphs, review snippets, sports league stats, ratings, product listings, AI overview, and more.

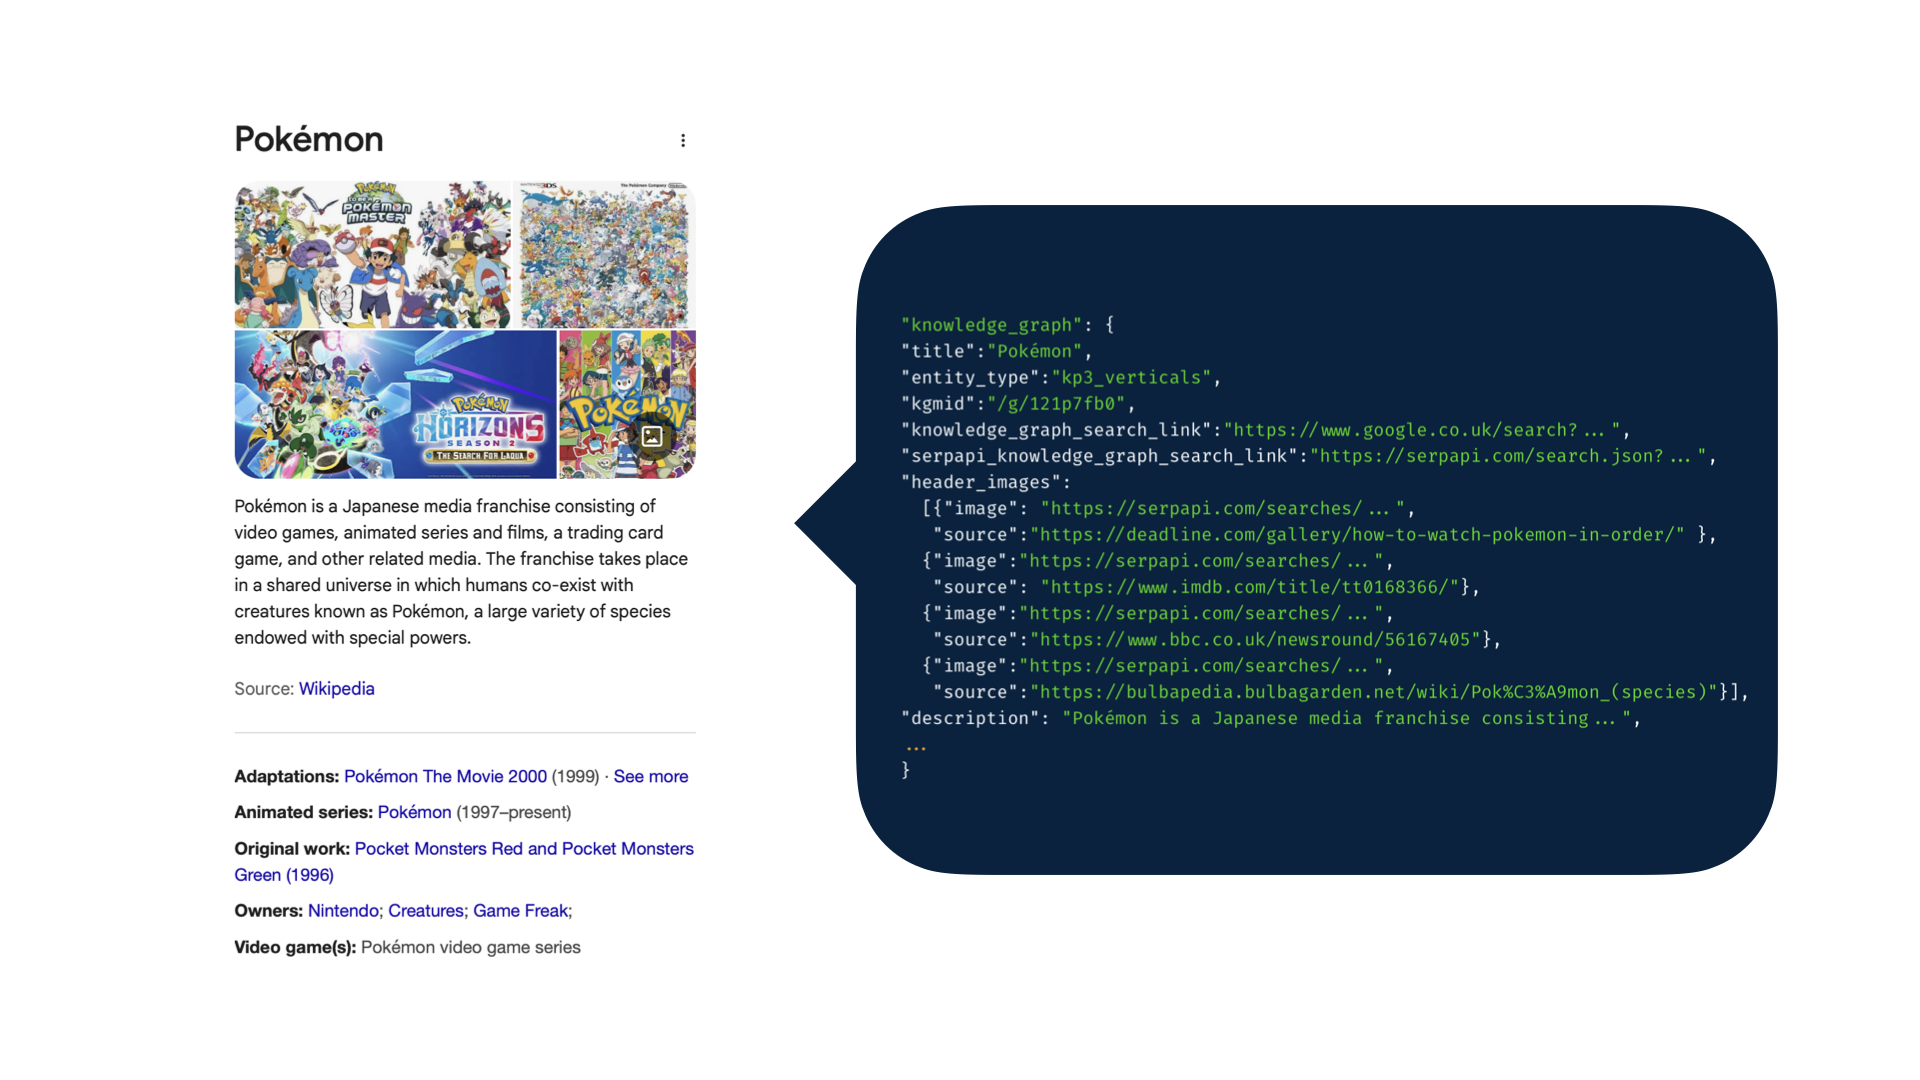
Example of SerpApi returning data in a JSON format.
SerpApi returns data in a JSON format, making it easy to integrate into your application. (Large preview)
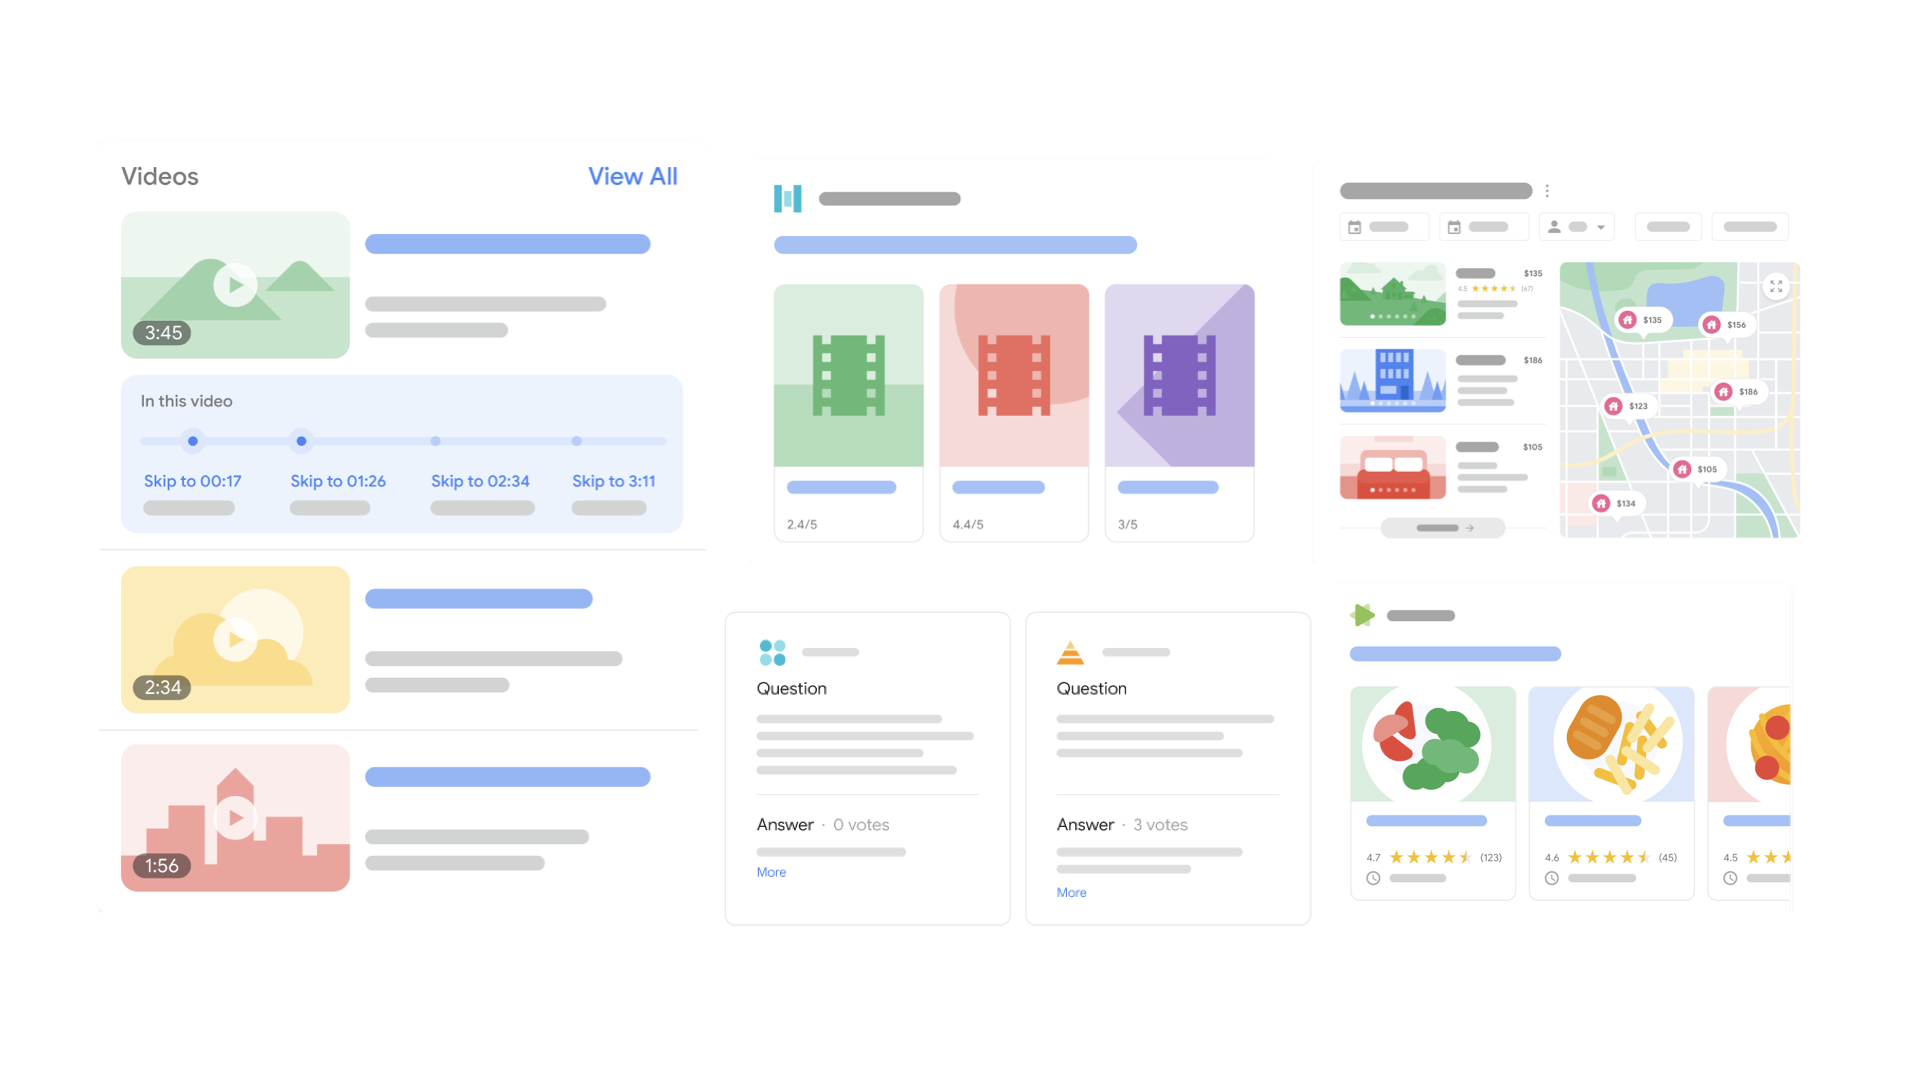
Various types of search engine results, such as meta related to video, audio, geolocation, questions, and recipes.
Various types of search engine results, such as meta related to video, audio, geolocation, questions, and recipes. (Large preview)

Speedy Results #

SerpApi’s baseline performance can take care of timely search data for real-time requirements. But what if you need more? SerpApi’s Ludicrous Speed option, easily enabled from the dashboard with an upgrade, provides a super-fast response time. More than twice as fast as usual, thanks to twice the server power.

There’s also Ludicrous Speed Max, which allocates four times more server resources for your data retrieval. Data that is time-sensitive and for monitoring things in real-time, such as sports scores and tracking product prices, will lose its value if it is not handled in a timely manner. Ludicrous Speed Max guarantees no delays, even for a large-scale enterprise haul.

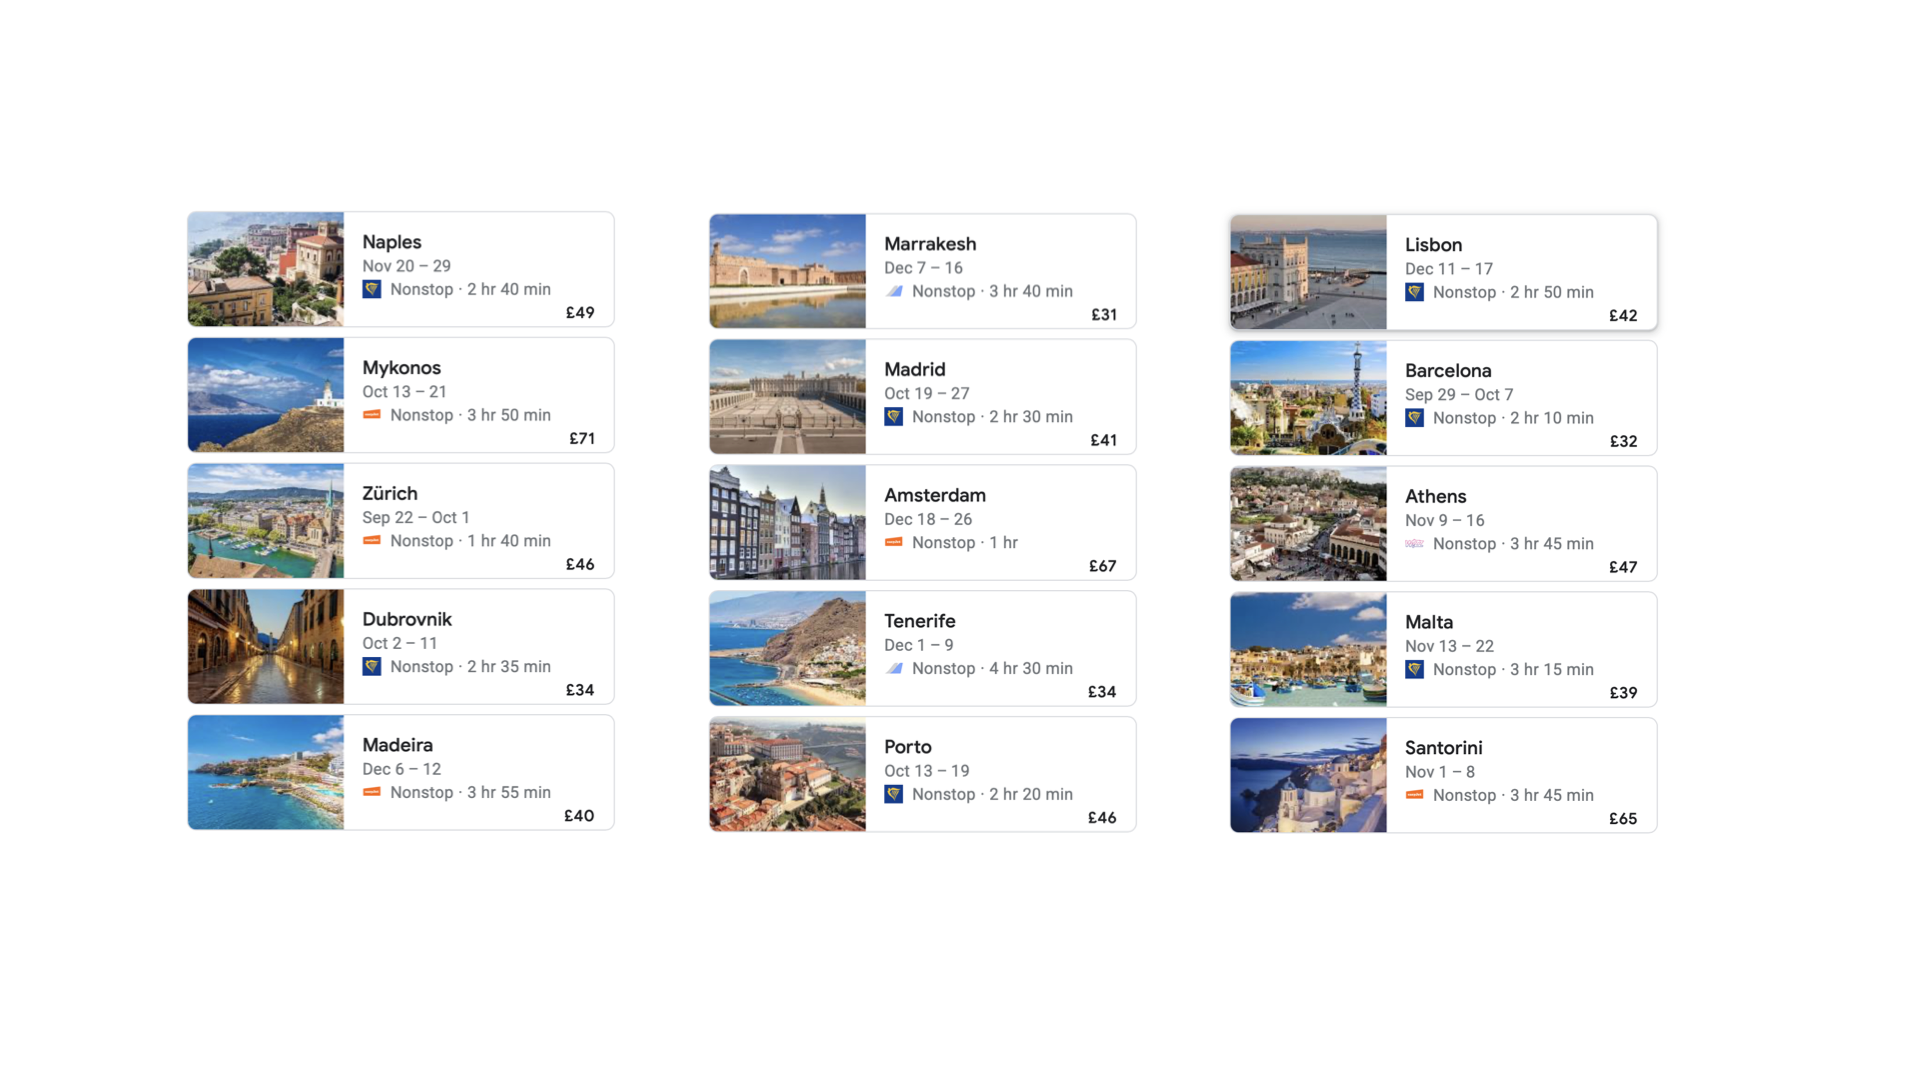
A list of flight prices from Google Flights
A list of flight prices from Google Flights. (Large preview)

You can also use a relevant SerpApi API to hone in on your relevant category, like Google Flights API, Amazon API, Google News API, etc., to get fresh and apt results.

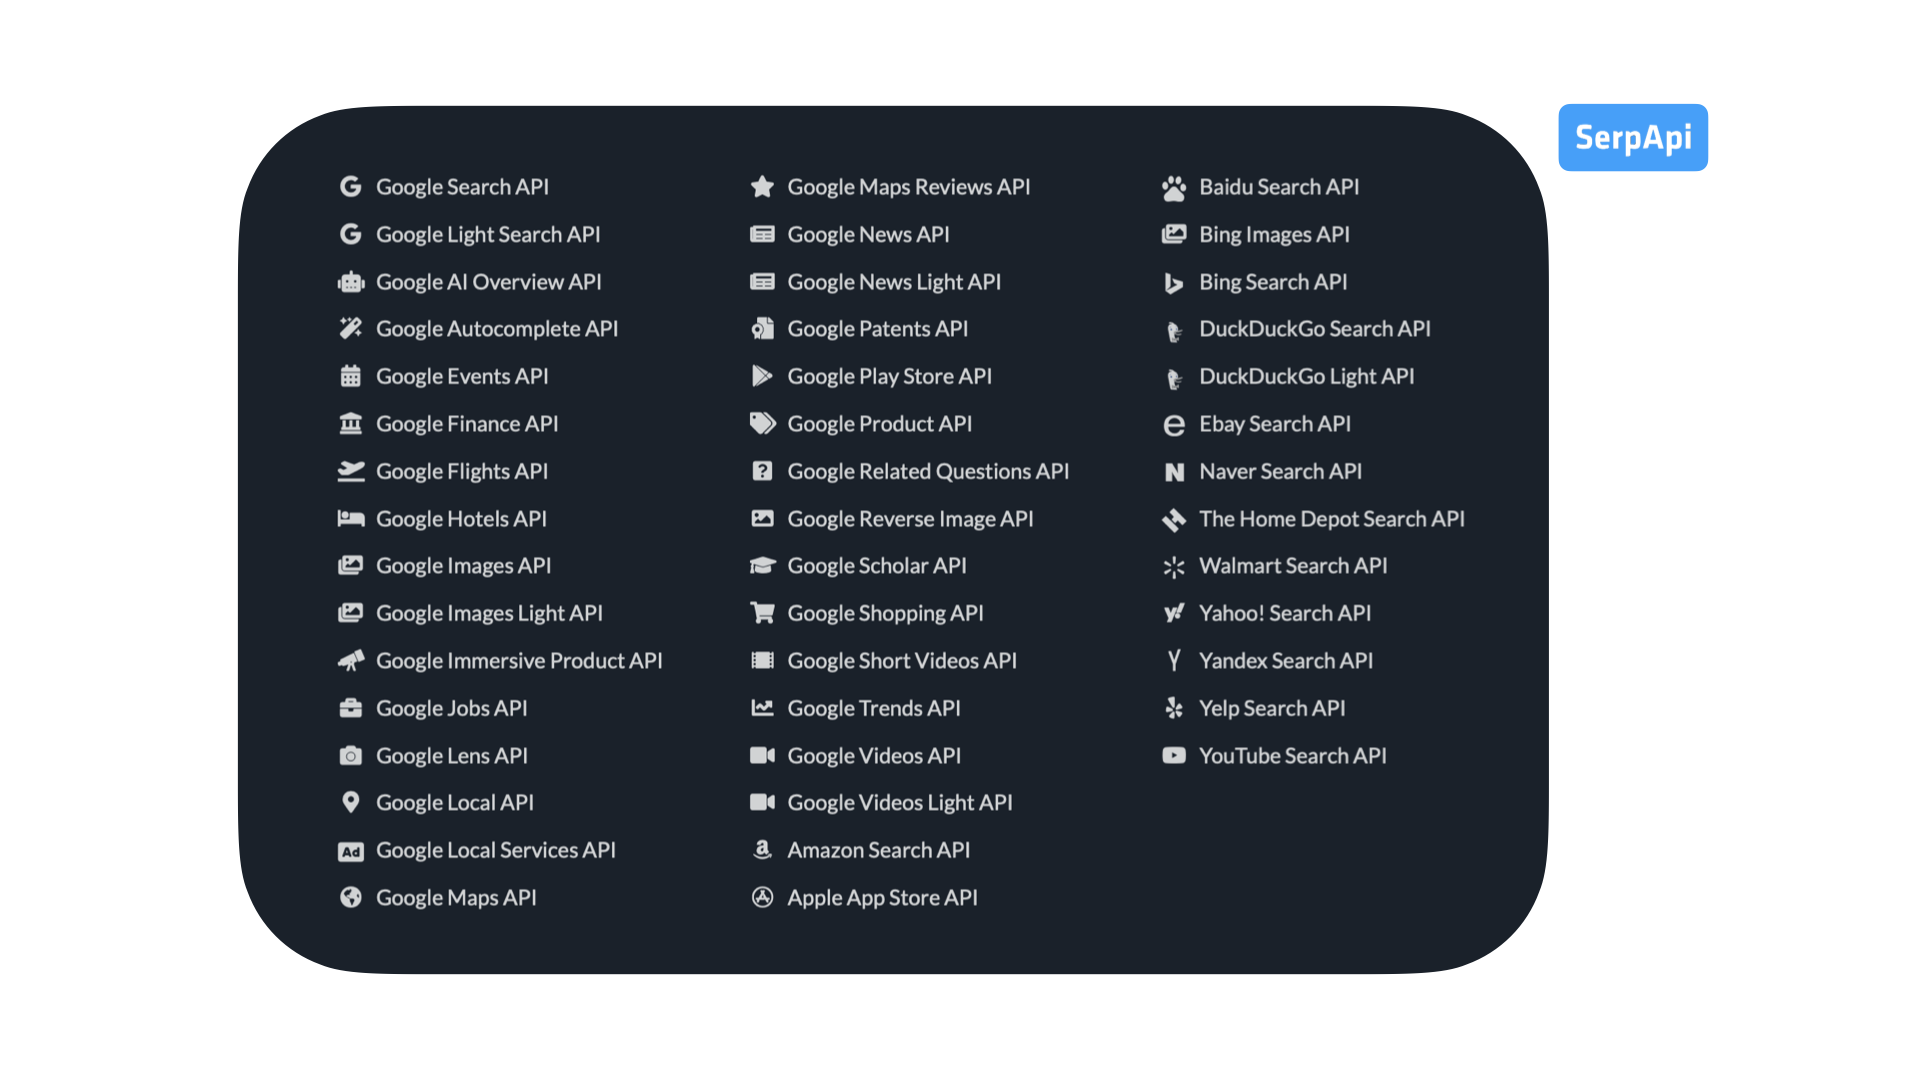
If you don’t need the full depth of the search API, there’s a Light version available for Google Search, Google Images, Google Videos, Google News, and DuckDuckGo Search APIs.

Three-column list of 45 Search APIs that are supported by SerpApi
(Large preview)

Search Controls & Privacy

Need the results asynchronously picked up? Want a refined output using advanced search API parameters and a JSON Restrictor? Looking for search outcomes for specific devices? Don’t want auto-corrected query results? There’s no shortage of ways to configure SerpApi to get exactly what you need.

Additionally, if you prefer not to have your search metadata on their servers, simply turn on the “ZeroTrace” mode that’s available for selected plans.

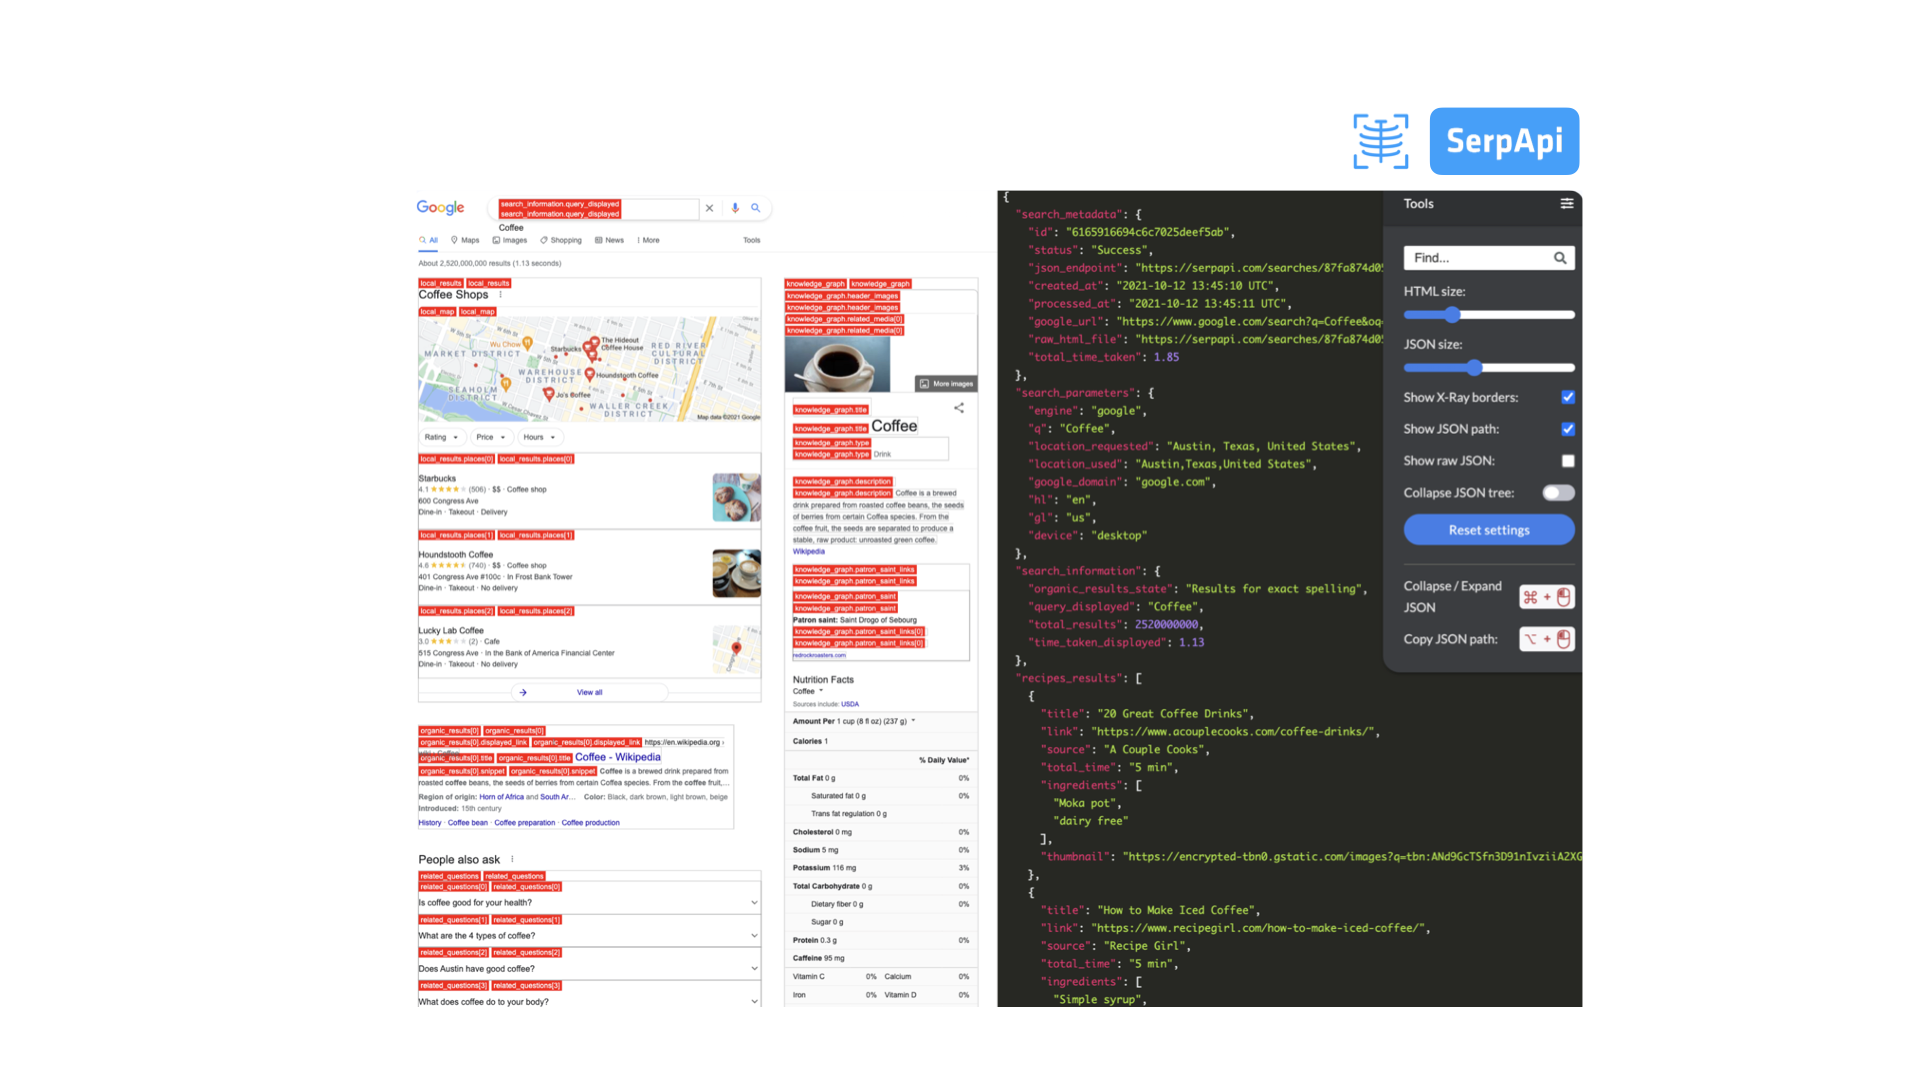
The X-Ray #

Save yourself a headache, literally, trying to play match between what you see on a search result page and its extracted data in JSON. SerpApi’s X-Ray tool shows you where what comes from. It’s available and free in all plans.

SerpApi’s X-Ray tool
(Large preview)

Inclusive Support

If you don’t have the expertise or resources for tackling the validity of scraping search results, here’s what SerpApi says:

“SerpApi, LLC assumes scraping and parsing liabilities for both domestic and foreign companies unless your usage is otherwise illegal”.

You can reach out and have a conversation with them regarding the legal protections they offer, as well as inquire about anything else you might want to know about, including SerpApi in your project, such as pricing, performance expected, on-demand options, and technical support. Just drop a message at their contact page.

In other words, the SerpApi team has your back with the support and expertise to get the most from your fetched data.

Try SerpApi Free

That’s right, you can get your hands on SerpApi today and start fetching data with absolutely no commitment, thanks to a free starter plan that gives you up to 250 free search queries. Give it a try and then bump up to one of the reasonably-priced monthly subscription plans with generous search limits.

Sunday, April 24, 2022

Evaluating the Robustness of OCR Systems

 evaluating the robustness of OCR systems (such as Tesseract or Google’s Cloud Vision) when adversarial samples are presented as inputs. It’s somewhere in-between fuzzing and adversarial samples crafting, on a black box, the main objective being the creation of OCR-proof images, with minimal amounts of noise.

It’s an old project that I recently presented at an International Security Summer School hosted by the University of Padua. I decided to also publish it here mainly because of the positive feedback received when presented at the summer school.

I’ll try to focus on methodology and results, which I consider being of interest, without diving into implementation details.

I published this ~1 year ago - not sure if it still works as described here. Hopefully it does, but I’m pretty sure Google made changes to the Vision engine since then.

Motivation

Let’s start with what I considered to be plausible use cases for this project and what problems it would be able to solve.

  • Confidentiality of text included in images? – It is no surprise to us that large services (that’s you, Google) will scan hosted images for texts in order to improve classification or extract user information. We might want some of that information to remain private.

  • Smart CAPTCHA? – This aims to improve the efficiency of CAPTCHAs by creating images which are easier to read by humans, thus reducing the discomfort, while also rendering OCR-based bots ineffective.

  • Defense against content generators? – This could serve as a defense mechanism against programs which scan documents and republish content (sometimes using different names) in order to gain undeserved merits.

Challenges

Now, let’s focus on the different constraints and challenges:

1. Complex / closed-source architecture

Modern OCR systems are more complex than basic convolutional neural networks as they need to perform multiple actions (e.g.: deskewing, layout detection, text rows segmentation), therefore finding ways to correctly compute gradients is a daunting task. Moreover, many of them do not provide access to source code thus making it difficult to use techniques such as FGSM or GANs.

2. Binarization

An OCR system usually applies a binarization procedure (e.g.: Otsu’s method) to the image before running it through the main classifier in order to separate the text from the background, the ideal output being pure black text on a clean white background.

This proves troublesome because it restricts the samples generator from altering pixels using small values: as an example, converting a black pixel to a grayish color will be reverted in the binarization process thus generating no feedback.

3. Adaptive classification

This is specific to Tesseract, which is rather deprecated nowadays - still very popular, though. Modern classifiers might be using this method, too. It consists of performing 2 iterations over the same input image. In the first pass, characters which can be recognized with a certain confidence are selected and used as temporary training data. In the second pass, the OCR attempts to classify characters which were not recognized in the first iteration, but using what it previously learned.

Considering this, having an adversarial generator which alters one character at a time might not work as expected since that character might appear later in the image.

4. Lower entropy

This refers to the fact that the input data is rather ‘limited’ for an OCR system when compared to… let’s say object recognition. As an example, images which contain 3D objects have larger variance than those which contain characters since the characters have a rather fixed shape and format. This should make it more difficult to create adversarial samples for character classifiers without applying distortions.

A direct consequence is that it greatly restricts the amount of noise that can be added to an image so that the readability is preserved.

5. Dictionaries

OCR systems will attempt to improve their accuracy by employing dictionaries with predefined words. Altering a single character in a word (i.e.: the incremental approach) might not be effective in this case.

Targeted OCR Systems


Tested locally on Tesseract 4.0 and remotely on Google’s Cloud Vision OCR

For this project, I used Tesseract 4.0 for prototyping and testing, as it had no timing restrictions and allowed me to run a fast, parallel model with high throughput so I could test if the implementation works as expected. Later, I moved to Google’s Cloud Vision OCR and tried some ‘remote’ fuzzing through the API.

Methodology

A rather simplified view of the flow; a feedback-based adversarial samples generator (in image: obfuscator) alters inputs in order to maximize the error of the OCR system

In order to be able to cover even black box cases, I used a genetic algorithm guided by the feedback of the targeted OCR system. We observe that the confidence of the classifier, alone, is not a good metric for this problem, a score function based on the Levenshtein distance and the amount of noise is employed.

One of the main problems here was the size of the search space which was partially solved by identifying regions of interest in the image and focusing only on these. Also, lots of parameter tuning…

Noise properties

Given the constraints, the following properties of the noise model must be matched:

  • high contrast – so it bypasses the binarization process and generates feedback
  • low density – in order to maintain readability by exploiting the natural low-filtering capability of the human vision

Applying salt-and-pepper noise in a smart manner will, hopefully, satisfy the constraints.

Working modes

Different working modes for small and large characters, in order to preserve readability. Both managed to entirely hide the given text when tested on Tesseract 4.0

Initially, the algorithm worked using only overtext mode, which applied noise in the rectangle which contained characters. However, this method is not the best choice for texts written using smaller characters mainly because there are less pixels that can be altered thus drastically lowering the readability even with minimal amounts of noise. For this special case, the decision to insert the noise in-between the text rows (artifacts) was taken in order to preserve the original characters. Both methods presented similar success rates in hiding texts from the targeted OCR system.

Just for fun, here’s what happens if the score function is inverted, which translates as “generate an image with as much noise as possible, but which can be read by OCR software”. Weird, but it’s still recognized…

Results on Tesseract

Promising results were achieved while testing against Tesseract 4.0. In the following figure is presented an early (non-final) sample in which the word “Random” is not recognized by Tesseract:

Tests on Google’s Cloud Vision Platform

This is where things get interesting.

The implemented score function can be maximized in 2 ways: hiding characters or tricking the OCR engine into adding characters which shouldn’t be there.

One of the samples managed to create a loop in the recognition process of Google’s Cloud Vision OCR, basically recognizing the same text multiple times. No DoS or anything (or I’m not aware of it), I’m still not sure if the loop persisted or not - it either produced a small number of iterations, failed (timed out?) or they had load balancers which compensated for this and used different instances.

Possible loop in the recognition process: the same text gets recognized multiple times. The bottom-left and the top-right corners are ‘merged’ into an oblique text row so the recognition process is sent back to already processed text.

Let’s take a closer look at the sample: below, you can see how the adversarial sample was interpreted by Google’s Cloud Vision OCR system. The image was submitted directly to the Cloud Vision platform via the “Try the

Rectangles returned by Cloud Vision indicate that additional text rows are ‘created’ during the recognition thus creating a loop

Also the ‘boring’ case where the characters ar

Once again, using the artifacts mode on a small text since larger texts are way easier to hide

Conclusions

It works, but the project reached its objective and is no longer in development. It seems difficult to create samples that work for all OCR systems (generalization).

Also, the samples are vulnerable to changes at the preprocessing stage in the OCR pipeline such as:

  • noise filtering (e.g.: median filters)
  • compression techniques (e.g.: Fourier compression)
  • downscaling->upscaling (e.g.: Autoencoders)

However, we can conclude that, using this approach, it is more challenging to mask small characters without making the text difficult to read. I compiled the following graph, in which are compared: the images generated by the algorithm (below 7% noise density) and a set of images that contain random noise (15% noise density). The 2 sets contain different images with characters of sizes: 12, 21, 36, 50. Each random noise set contains 62 samples for each size - average values were used.

Noise efficiency is computed by taking into account the Levenshtein distance and the total amount of noise in the image.

Interesting TODO’s

  • Extracting templates from samples and training a generator?
  • Exploiting directly the row segmentation feature?
  • Attacking Otsu’s binarization method?

Maybe someday…

Cite

Should you find this relevant to your work, you can cite the article using:


@inproceedings{sporici2018evaluation,
  title={An Evaluation of OCR Systems Against Adversarial Machine Learning},
  author={Sporici, Dan and Chiroiu, Mihai and Cioc{\^\i}rlan, Dan},
  booktitle={International Conference on Security for Information Technology and Communications},
  pages={126--141},
  year={2018},
  organization={Springer}
}

As characters get smaller, the efficiency of the noise added by the algorithm decreases - the random noise samples behave in an opposite manner.

API” option so, at the moment of testing, the results could be easily reproduced.


Improving Tesseract 4's OCR Accuracy through Image Preprocessing


In this work I took a look at Tesseract 4’s performance at recognizing characters from a challenging dataset and proposed a minimalistic convolution-based approach for input image preprocessing that can boost the character-level accuracy from 13.4% to 61.6% (+359% relative change), and the F1 score from 16.3% to 72.9% (+347% relative change) on the aforementioned dataset. The convolution kernels are determined using reinforcement learning; moreover, to simulate the lack of ground truth in realistic scenarios, the training set consists of only 30 images while the testing set includes 10,000.

The dataset in cause is called Brno Mobile, and contains colored photographs of typed text, taken with handheld devices. Factors such as blurriness, low resolution, contrast, brightness are contributing to making the images challenging for an OCR engine.

Resized image from the Brno dataset which contains text that was not recognized by Tesseract 4 during the evaluation (an empty string was returned)

During this experiment, the out of the box version of Tesseract 4 has been used, which implies:

  • no retraining of the OCR engine
  • no lexicon / dictionary augmentations
  • no hints about the language used in the dataset
  • no hints about segmentation methods; default (automatic) segmentation is used
  • default settings for the recognition engine (LSTM + Tesseract)

Problem Analysis

Tesseract 4 has proven great performance when tested on favorable datasets by achieving good balance between precision and recall. It is presumed that this evaluation is performed on images that resemble scanned documents or book pages (with or without additional preprocessing) in which the number of camera-caused distortions is minimal. Tests on the Brno dataset led to much worse performance that will be discussed later in the article.

In the above figure, a high precision indicates favorable True-Positives to False-Positives ratio thus revealing proper differentiation between characters (i.e. a relatively small number of misclassifications). Despite this, almost no improvements in recall can be observed when switching from the base classification method to the Long Short-Term Memory (LSTM) based Convolutional Recurrent Neural Network (CRNN) for sequence to sequence mapping.

“Despite being designed over 20 years ago, the current Tesseract classifier is incredibly difficult to beat with so-called modern methods.” - Ray Smith, author of Tesseract

I assume that further training for different fonts might not provide significant improvements and neither will a different model of classifier. Is there a chance that the classifier doesn’t receive the correct input?

It was pointed out in a previous article that Tesseract is not robust to noise; certain salt-and-pepper noise patterns disrupt the character recognition process, leading to large segments of text being completely ignored by the OCR engine - the infamous empty string. From empirical observations, these errors seem to occur either for a whole word or sentence or not at all thus suggesting a weakness in the segmentation methodology.

The existence of similar behavior, given images which present more natural distortions, is questioned - hence this experiment.

Black-box Considerations

Since analyzing Tesseract’s segmentation methods is a daunting task, I opted for an adaptive external image correction method. To avoid diving into Tesseract 4’s source code, the OCR engine is considered a black-box; in this case, an unsupervised learning method must be employed. This ensures easier transitions to other OCR engines as it doesn’t directly rely on concrete implementations but only on outputs - at the cost of processing power and optimality.

Proposed Solution

The solution consists in directly preprocessing images before they are fed to Tesseract 4. An adaptive preprocessing operation is required, in order to properly compensate for any image features that cause problems in the segmentation process. In other words, an input image must be adapted so it complies with Tesseract 4’s preferences and maximizes the chance of producing the correct output, preferably without performing down-sampling.

I choose a convolution-based approach for flexibility and speed; other articles tend to perform more rigid image adjustments (such as global changes in brightness, fixed-constant conversion to grayscale, histogram equalization, etc.). I preferred an approach that can properly learn to highlight or mask regions of the image according to various features. For this, the kernels are optimized using reinforcement learning using an actor-critic model. To be more specific, it relies on Twin Delayed Deep Deterministic Policy Gradient (TD3 for short), for discovering features which minimize the Levenshtein distance between the recognized text and the ground truth. I’ll not dive into implementation details of TD3 here as it would be somehow out of scope but think of it as a method of optimizing the following formula:

Where

is a kernel, and

is a tuple from the training set.

A short (simpler) proof of concept of the convolutional preprocessor is presented in this Google Colab. It uses a different architecture than the final one and has the purpose of verifying if the idea of using convolutions is feasible and offers good results. A comparison is presented between original and preprocessed images including recognized texts for each sample.

The final model is illustrated below, with ReLU activations after each convolution to capture nonlinearities and prevent having negative values as pixels’ colors.

To properly compensate for image coloring and reduce the number of channels (R, G, B), 1x1 convolutions are used. This prevents overfitting up to a point while also ensuring grayscale output. Further convolutions are applied only on the grayscale image.

Symmetry constraints are additionally enforced for each 3x3 kernel in order to minimize the number of trainable parameters and avoid overfitting. This means that for a 3x3 kernel only 6 variables out of 9 must be determined while the rest can be generated through mirroring. Below are the values I got for the five kernels (bold to emphasize symmetry):

#1 #2     #3    
0.7 0.2573 -0.3 0.3 0.3 -0.2996 0.3
1.3 0.3 1.3 -0.295 0.3 1.2949 0.3
1.3 0.2573 -0.3 0.3 -0.2802 0.2922 -0.2802


Comparison

I used 10,000 images from the testing set for the evaluation of the current methodology and compiled the following graphs. The differences between original and preprocessed samples are illustrated with three metrics of interest: Character Error Rate (CER), Word Error Rate (WER) and Longest Common Subsequence Error (LCSE). In this article, LCSE is computed as follows:

Additionally, I plotted everything in histogram format to properly see the distributions of errors. For CER and WER, it is easy to observe the spikes around 1 (100%) that suggest the aforementioned segmentation problem (at block-of-text level) produces the most frequent error (empty strings are returned so all characters are wrong). In certain situations, the WER is larger than 1 because the preprocessing step introduces artifacts near the border of the image thus leading to recognition of non-existent characters. When looking at the LCSE plot, a distribution shift can be seen from the original approximately gaussian shape with its peak (mode) near the average number of characters in an image (56.95) to a more favorable shape with overall lower error rates.

A numeric comparison is presented below:

Metric Original (Avg.) Preprocessed (Avg.)
CER 0.866 0.384
WER 0.903 0.593
LCSE 48.834 24.987
Precision 0.155 0.725
Recall 0.172 0.734
F1 Score 0.163 0.729

Takeaways

Significant improvements can be observed through this preprocessing operation. Moreover, the majority of errors probably do not occur in the sequence to sequence classifier (since all the recognized characters are erroneous and would contradict previous performance analysis). A page-segmentation issue when automatic mode is used seems more plausible. It is shown that an array of convolutions is sufficient, in this case, to decrease error rates substantially.

The OCR performance on the preprocessed images is overall better but not good enough to be reliable. A 38% character error rate is still a large setback. I’m pretty sure that better recognitions can be obtained with more fine-tuning, a more complex architecture for the convolutional preprocessor and a more diverse training set. However, the current implementation is already very slow to train which makes me question if the entire methodology is feasible from this point of view.

Cite

If you found this relevant to your work, you can cite the article using:


@article{sporici2020improving,
  title={Improving the Accuracy of Tesseract 4.0 OCR Engine Using Convolution-Based Preprocessing},
  author={Sporici, Dan and Cușnir, Elena and Boiangiu, Costin-Anton},
  journal={Symmetry},
  volume={12},
  number={5},
  pages={715},
  year={2020},
  publisher={Multidisciplinary Digital Publishing Institute}
}


#4     #5    
-0.2793 0.2395 0.2885 -0.294 -0.2905 -0.2939
0.2395 0.7119 0.3 0.3 1.162 -0.2905
0.28850.3-0.2828-0.23280.3-0.294


Sunday, July 6, 2014

Facing Your Fears: Approaching People For Research

When working on a project, have you ever felt that you and the rest of the team were making a lot of decisions based on assumptions? Having to make choices with limited information is not unusual — especially in complex projects or with brand new products.
Phrases like “We think people will use this feature because of X” or “We believe user group Y will switch to this product” become part of the early deliberation on what to develop and how to prioritize. At some point, though, these phrases start to feel like pure guesses and the ground under your feet feels shaky. What can you do about it?
Regardless of your role in the project, one activity in particular will help your whole team build a solid foundation for product strategy and design: that is, approaching potential users for research, such as interviews and usability tests.
Such research is an important aspect of user-centered design. It helps you build products that are rooted in a deep understanding of the target audience. Among other benefits, interviewing potential users helps you achieve the following:
  • more precisely define who the target audience is (and isn’t),
  • face and challenge your assumptions,
  • uncover unmet needs,
  • discover the behaviors and attitudes of potential users firsthand.
You can conduct informal yet valuable user research yourself with practice and with guidance from great sources like Steve Portigal’s Interviewing Users and Steve Krug’s Rocket Surgery Made Easy. One thing that stops a lot of people from trying their hand at research isn’t just lack of experience, but a fear of approaching people and asking for their time. This obstacle is greater than many would care to admit.

The Difficulty Of “Face To Face”

I was teaching an experience design class in high school when it really hit me. Students were engaged in the design process until they were told that they had to request interviews from strangers. The anxiety levels went through the roof! A look of shock covered their faces. Shortly after, two of the students asked to receive a failing grade on the activity rather than have to face strangers (a request that was not granted)!
This was no longer a case of time, opportunities, resources or priorities. The interviews were a part of the class and were considered essential. The students were presented with a clear set of expectations, provided with aid in planning and writing questions, and taken to the location (a college) to conduct the interviews.
When all of the usual obstacles were removed, what was laid bare? A strong fear of approaching strangers, made even stronger by the fact that so many interactions nowadays are done online, rather than face to face. Ask someone to create an online survey and they’re all over it — ask that same person to pose those same questions to a stranger face to face and they’ll freeze up.
One might assume that the problem afflicts only those in high school, but such a deep-seated reaction is felt by many working adults who are suddenly responsible for requesting something from strangers — even when the thing being requested is a relatively low commitment, like 10 minutes for an interview.
Are you at the point in a project when you would benefit from insights gained from face-to-face discussions with potential users but find yourself blocked by a fear of asking? Read on for techniques to help you approach people for research, the first step to gaining the knowledge you need.

“I’m Afraid I’ll Be Bothering People.”

I’m sure you’ve been approached by a stranger at one time or another. The negative occasions stand out the most, when you were annoyed or felt guilty because you didn’t want to say no to a request for money or personal information or a signature.
When a stranger approaches, the person being approached has several concerns at once:
  • “Who is this person?”
  • “Are they trying to scam me?”
  • “Are they going to ask me for money?”
  • “Are they going to ask me to sign something that I don’t agree with?”
  • “Am I going to have to figure out how to get rid of them?”
  • “How long is this going to take?”
Your memories of being approached could make you uncomfortable if you’re the one approaching others.
The good news is that approaching people for interviews can be a lot easier than requesting a donation. If you make it clear quickly that their time is voluntary and that you won’t ask for anything they don’t want to give, then you’ll generally get a positive response. After all, you’re not asking people for money, just for their time and attention. Time is valuable, but its value varies according to the person’s situation at that moment — and you can do certain things to communicate the value of agreeing to your request.

Increase the Value of Participation

Interview requests are accepted when participation is perceived to be as or more valuable than what the person is doing at the time. People calculate that value in their heads when you ask for their time.
Below are some of the factors that can swing the calculation in your favor.

Find the Right Time

If someone is in a rush to get somewhere, then making your research seem more valuable than their desire to get to their destination will probably be difficult. Someone who is walking briskly, looking tense and not making eye contact is not the ideal candidate.
Approach people who appear to be one or more of the following:
  • Between tasks
    If you’re asking about a particular activity, go to areas where people tend to be finishing up that activity, and talk to them as soon as they’re done with it. You’ll get a fresh perspective on the whole experience, and they likely won’t be in a rush to get to their next activity. For example, if you want to interview runners, wander the finish line of a race. Look for runners who are cooling down and checking out their swag but not yet heading home.
  • Bored
    Waiting in line, waiting for a bus or waiting for an elevator — if someone seems to be idly swiping their phone or staring off into space, they might actually welcome a distraction.
  • Procrastinating
    Some activities take a long time. The human brain needs a change of focus every now and then, and your research could be just the thing. If your target audience is students, visit a study area. When a student comes up for air, ask for some time. They might need the mental break!
Regardless of whom you approach, give them an idea of how long the interview will take (about 10 minutes, for example), so that they can do the mental math of calculating the value of saying yes.

Be Aware of Body Language

As mentioned, pay attention to the candidate’s body language. Do they seem tense? Are they frowning at their phone? Are they power-walking? They might be late for a meeting, so the timing would be wrong. Someone gazing around or strolling casually is a better bet. People on phones are a bit harder to read because many check their phone when bored or procrastinating — still, their facial expression might tell you whether they’re open to being interrupted for something more interesting.
Your own body language is important, too. Planting yourself in the middle of a person’s path and facing them squarely will come off as aggressive, likely triggering a negative reaction. They might feel like they’d have a hard time getting rid of you if they’re not comfortable with your request.
Approach within clear view, but from the side. Also, try angling your body slightly away from the person. You want to seem engaged but also make them feel like they could end the conversation if desired. This will give them a greater sense of control and increase the likelihood that they’ll give you those precious seconds you need to make your request.

Fostering Interest

The feeling one gets from participating in research can be rewarding in itself. Interest is one positive feeling that leads people to say yes to research, which you can emphasize when approaching strangers.
Mention early on that you’re conducting research, which makes clear that you’re not asking for money and tends to generate interest.
Being approached to participate in research is fairly unusual for most people. The fact that you’re conducting a study might inspire a healthy curiosity. People will often be curious about what topic is being researched, what kinds of questions might be asked, and what they might find out about themselves in answering. The prevalence of quizzes and personality tests online is a good indication of this interest; those researchers are gathering data from the tests, but many of the respondents feel like they are learning about themselves (and potentially others) by considering the questions being asked.
The person might not be expecting to learn whether they’re a “benevolent inventor” or an ENFP by the end of the interview, but they might still find your questions interesting to consider.
Will the interviewees be shown something that others don’t have access to yet, like a new product or campaign? If so, bring that up quickly. It really boosts curiosity!
Furthermore, people might be flattered that you’re interested in their thoughts and opinion. Build on that! If there’s a reason you approached that person, share it. If you’re interviewing people about healthy food choices near a health food store and you stop someone who has just purchased something at the store, you could mention that their interest in health is one reason you approached them. Stick to obvious observations — you don’t want to come across as creepy!

Fostering Goodwill

Donating to a cause feels good, and volunteering time for research is no different. If your efforts are for a worthy result, like making texting easier for the elderly, share that benefit.
Another magic phrase? “I’m a student.” If you are, say so quickly to allay the person’s suspicion about your motive. Your effort on the path of learning will appeal to their goodwill.
If you’re not a student and your topic doesn’t sound particularly socially relevant, people might still be willing to help out if they connect with you. If you’re friendly and enthusiastic about the topic, then they’re more likely to say yes.
To keep the goodwill flowing, express your gratitude for their time and thoughts. Let them know before and after the interview that their time will have a great impact on the success of the research.

Offer Incentives

This one might seem the most obvious: You can increase the value of participation by offering an incentive. A $10 or $20 gift card from a popular vendor like Amazon or Starbucks can incline someone to accept a 15 to 30 minute interview. As the inconvenience to the participant increases, so should the incentive — whether that inconvenience is the length of the interview, the location or the time of day.
The incentive doesn’t have to be monetary. Be creative in what you offer. It could be access to a service that most people don’t have or a fun gadget that’s related to your topic (like a pedometer if the topic is health).
Offering an incentive can be useful, but don’t let it turn into a crutch. The point is to get comfortable with approaching people; associating a cost with that adds pressure that you don’t need. Learning to request participation without an incentive — and learning to increase the perceived value of participation without one — will take the cost out of the equation. Nevertheless, if you’re conducting formal research with a specific audience for a lengthy period of time, offering an incentive is definitely a best practice.

“I’m Afraid Of Rejection.”

Rejection is people’s number one fear when approaching strangers. Hearing no has always been difficult, whether it’s a polite no or an angry no followed by a rant. Either way, it stings. Your response to that sting, though, is what matters. How do you explain the rejection to yourself, and does your explanation help or hurt you?
Martin Seligman, one of the originators of positive psychology, conducted a study in the ’70s that gives insight into the types of mindsets that make people feel helpless. Seligman found that those who exhibit long-term “learned helplessness” tend to view negative events as being personal, pervasive and permanent. In other words, if a person is rejected, they might rationalize that the rejection is a result of their own failing, that everyone else is likely to reject them as well, and that they can do nothing to lessen the likelihood of rejection.
When you prepare to approach someone, consider instead that, if they say no, they aren’t really rejecting you, but rather rejecting your request. It’s not personal. Maybe they’re in the middle of something, or maybe they’re just not in the mood to talk. The rejection is fleeting, and the next person might be perfectly happy to participate.
Even knowing this, your first attempt will be the most difficult. Think of it like jumping into a pool: The initial shock is certain, but you’ll quickly get used to the water and will be swimming in no time!

Turn It Into a Game

When my brother was in college, he had a friend — let’s call him Bob — who had been single for a long time. Bob wanted to develop his ability to approach a woman and strike up a conversation, but he constantly froze up because of his fear of rejection.
One night at a lively bar, the two of them decided to make a game of it. If an approach led to a conversation — fantastic! He got 1 point. If the approach led to rejection, he still got 1 point for making the attempt. This turned failure into a small win and encouraged Bob to try and try again. The person with the most points at the end of the night won a free drink from the other. This shifted the focus and value onto the attempt, not the result.
Try this technique with someone who also wants to practice approaching people for research. Award a point for each approach, and reward the winner. Choose a prize that you both value but that doesn’t outweigh the good feeling of a successful approach. Not that you want to be turned down, but it helps to have a reward for plucking up the courage to try.

Variation: Football Rules

If you find the incentive to approach is still not enough, award a field goal (3 points) for every unsuccessful approach and a touchdown (7 points) for each successful one. Because interviews take time, the person who is trailing in points could pull ahead even if they’re mostly getting rejections.

“Only Extroverts Are Good At This.”

Google tells us that an introvert is “a shy, reticent and typically self-centered person.” Not a pretty picture! (An extrovert is defined as “an outgoing, overtly expressive person” — a more positive description, at least in the US).
Introversion has been erroneously associated with characteristics like being “bad with people” or being unsuccessful in approaching others.
In psychology, the field that gave us the terms “introvert” and “extrovert” (thanks to Carl Jung), the definitions are fairly different. The focus is on how people recharge their energy. Introverts tend to recharge by spending time with their own thoughts and feelings; extroverts recharge with external stimulation, such as time with friends or adventures in new destinations.
Jung stated that, “There is no such thing as a pure introvert or extrovert. Such a person would be in the lunatic asylum.” We all fall somewhere along the continuum. It turns out that some of the most fantastic researchers out there fall almost in the middle (called “ambiverts”). They balance an extrovert’s drive to interact others with an introvert’s skill in observation and reflection.
Daniel Pink explores this in his book To Sell is Human, which summarizes a variety of studies that find no link between high extroversion and major success in sales. (Pink defines sales as “persuading, convincing and influencing others to give up something they’ve got in exchange for what we’ve got” — a broad definition that could include asking someone to give up their time to participate in research.)
In fact, in the studies Pink cites, such as one by Adam Grant of the University of Pennsylvania, the highly extroverted — who tend to talk too much and listen too little — performed only slightly better than the highly introverted. Who did the best by far? The ambiverts, who balanced a drive to connect with an ability to observe and inspect.
If you consider yourself an introvert, then you’re probably relieved to hear that you don’t have to swing to the other side of the scale to be successful in interviews. You can use your skill in observation to pay attention to the environment and identify people to approach. You might need to tap into your extroverted side to approach someone, but once the conversation begins, you can call on your skill in observing and listening intently. With practice, this introverted quality will become an important part of the process that leads to the payoff: generating important insights.
Let’s explore a few techniques to ease gently into the ambiversion zone, exercising your interviewing muscles!

Practice Playfully

Practice your requests with a friendly audience and in a comfortable location to make the experience more playful and less stressful. Learning and playing go together!
Set challenges for yourself that expand your skills but that don’t have serious consequences. Instead of waiting for an intense, highly visible project at work to make your first attempt at approaching people, give yourself a short interview challenge. Pick a friendly location and choose a topic of research that would be of interest to most interview candidates and whose results you would not formally present.
Can you think of a local restaurant or cafeteria? Try interviewing its employees about their experience with the lunchtime rush to identify ways to better manage lines (of course, wait until after the rush to approach them). Taking a taxi? Interview the cab driver about their use of technology and how it has changed in the last three years. Do this as though you were conducting research for a real project (for example, ask to interview them, rather than launching right into your questions).
Here are two introductions you can practice:
“Excuse me! I’m a student, and today I’m conducting research on ways to improve transportation information for commuters. Hearing about your experience would be really valuable. Do you have 10 minutes to answer some questions?”
“Hi! We’re conducting some research today. Would you like to be interviewed on your lunchtime eating habits? It’ll take about 10 minutes, and your thoughts will help us improve the availability of nutritional information.”

Make It Meaningful

Whether you’re interviewing for practice or for work, tap into the aspects of the topic that make it deeply meaningful and personal to you. Genuine enthusiasm for a topic is hard to fake and will override fear to a large extent.
Remember the high-school students who were so afraid of approaching people? The class ended up going through the research process a second time with different topics. Instead of being told to interview college students about financial planning, students picked their own topics, like helping other students complete their homework, eating healthier meals and handling peer pressure.
The class picked students to interview, a mixture of friends and strangers. Because they were passionate about the topics (and had practiced once already), the second round of requests was much easier.
Likewise, consider practicing with more than one round of interviews:
  • Round 1
    Choose a topic that you know will be of interest to the people you’re interviewing.
  • Round 2
    Choose a topic that you’re passionate about. (Try to be objective, though!)
  • Round 3
    Take on a challenge for a product or project with support from other team members. (See the section below, “Pair Up Personalities,” for an example.)
If you’re on a team that wants even more practice, you could take turns suggesting practice challenges for each other. The more you practice, the easier it gets — promise!

Pair Up Personalities

If you consider yourself an introvert, pair up with someone who considers themselves an extrovert, and play to each other’s strengths for the first few interviews.
Using your observational skill, you could identify candidates to interview, and the extrovert could approach the first three people.
After the first three or four approaches, take a break and share your techniques with each other. You could share your insight from observing the environment and suggest tips on which people in which location might be best to approach. The extrovert could share tips on conversation openers that seem to be working well. When you’re both comfortable, switch roles to exercise the other’s skills.
This method situates you as mentors to each other, bringing you both closer to the middle of the introversion-extroversion scale.

Go Face To Face

Now that you’ve learned some techniques to get started, don’t let another week go by without trying one of them out! A good first step? Think of topics that you’re passionate about, the ones that are intriguing enough to propel you forward. You’ll find that the skills you develop will give you confidence to pursue the answers you need, leading you to better experiences for yourself and others.